Embeddings#
How text and multimodal embedding models are trained, searched and used for retrieval, plus attempts to make embeddings interpretable.
About this chapter
An embedding model maps an input, usually text, to a vector so that search becomes a nearest-neighbor lookup. The chapter starts with how models differ (bi-encoder, late interaction, cross-encoder) and how they are trained: a staged pipeline ending in contrastive finetuning, the InfoNCE and sigmoid losses, and a long list of tricks at training, indexing and query time. A timeline of top models follows, from BM25 and averaged word vectors through contrastively trained and LLM-initialized models to multimodal ones.
The middle covers search itself: benchmarks, agentic search where an agent runs many queries (sometimes with grep instead of vectors), and the index structures that make nearest-neighbor search fast, each with an index-time and a query-time figure. The last sections are about what is built on top of or learned from embeddings: interpretable embeddings built from yes/no questions, RAG, shared representations across models, recovering text from its embedding, and external memory for LLMs.
Chapter outline: 14 sections
- Overviews
- Embedding model distinctions1 figureThe main design choice is where the query and document first interact.
- Best practices for trainingThe tricks are grouped by when they act: while training the model, while embedding the documents, and at query time.
- Losses1 interactiveBoth losses pull a query toward its positive and away from negatives.
- Top-performing modelsRoughly in historical order: simple baselines, bi-encoders like SBERT, contrastive pre-training with synthetic data and instructions, then models initialized from a pre-trained LLM.
- Papers with a little trickSingle changes to an embedding model, grouped by when they act: during pre-training (masked autoencoding), during training (one model for generation and embeddings, Matryoshka prefixes that work as smaller embeddings), after training, or at query time (repeating the input so the second copy sees all of it).
- Datasets / benchmarksMTEB is the standard leaderboard but may be overfit: paraphrasing its test sets lowers scores.
- Agentic searchHere retrieval is one tool in a loop: an agent plans searches, reads results and searches again.
- Searching embeddings (approximate nearest neighbor)12 figuresExact nearest-neighbor search compares the query with every stored vector.
- Explainable embeddingsMost of these build an embedding whose dimensions mean something, usually answers an LLM gives to yes/no questions about the text.
- Retrieval augmented generation (RAG)The table from the RAG perspective paper sorts systems by what they retrieve (chunks, tokens, phrases), where it enters the model, how often retrieval happens, and whether the retriever and LM are trained jointly.
- Universal representationsEvidence that different models learn similar representations, from shared SAE features and neurons to translating embeddings between models without paired data.
- Embedding inversionsAn embedding can leak its input: these methods recover the text from an embedding, or the prompt from a model's outputs.
- External memory enhancements for LLMsWays to give an LLM memory beyond its context window: a kNN index over past context, a datastore read at inference time, a separate model trained on a corpus in place of retrieval, or a memory matrix the network reads and writes.
See related papers in the 📌 llm basics and 📌 llm research pages.
Embedding models take in unstructured input (here, often text) and transform it into a vector representation that is usually used for search. Key considerations include: fast inference for embedding a new input, small/quantized embeddings for efficient storage, indexability for fast search with retrieval algorithms.
Overviews#
detailed overview of info retrieval (bruch, 2024)
introductory blog post on embeddings
Embedding model distinctions#
The main design choice is where the query and document first interact. Encoding them separately makes documents indexable ahead of time; encoding them together is more accurate but has to run for every query-document pair.
leading models as of summer 2026: google (gemini embedding), voyage (voyage series, open-source voyage-4-nano), alibaba (qwen embedding, GTE), cohere, openai (relatively outdated), BAAI (BGE), Jina (bought by elastic), NVIDIA (NV-Embed), Microsoft (E5), nomic (nomic-embed)
embedding approaches
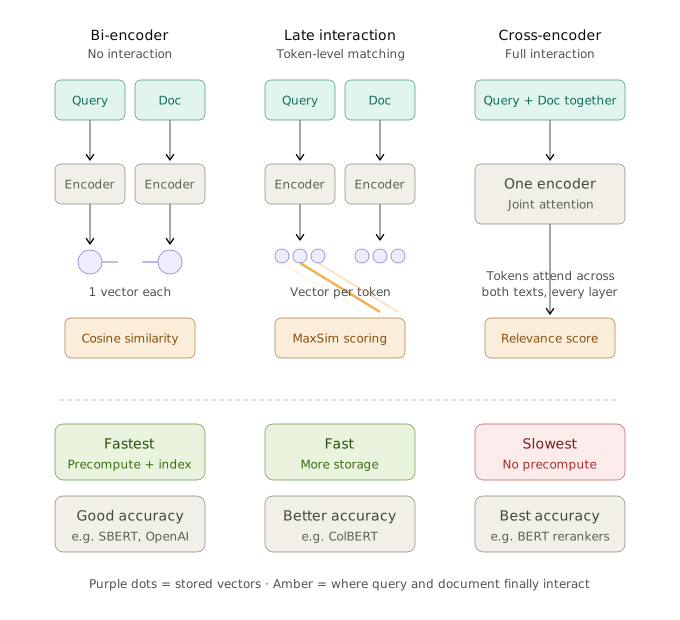
Fig. 150 Figure 1. Three levels of interaction between query and document. A bi-encoder embeds them separately into one vector each, late interaction keeps a vector per token and compares them at the end, and a cross-encoder reads both together.#
3 levels of interaction
bi-encoder: separately encode query & doc into a single vec
late-interaction encoder: separately encode but keep a vector per token & learn some params on how to compute similarity between them
e.g. ColBERT (khattab & zaharia, 2020) uses maxsim to compare, which keeps the vector for each token and then for each token in the query, finds the candidate token it matches best (highest cosine similarity), then averages those best-match scores across all query tokens
Your Embedding Model is SMARTer Than You Think (zhang…lee, 2026) - use the maxsim score (along with the original last-token score) to do late interaction without requiring post-training
cross-encoder: encode query and doc together
Best practices for training#
The tricks are grouped by when they act: while training the model, while embedding the documents, and at query time. Rerankers and query expansion cost nothing at training time but add latency per query.
basic training pipeline
standard self-supervised pre-training, e.g. BERT or off-the-shelf model like Qwen
weak unsupervised pre-training, e.g. weakly related text pairs, such as QA pairs from forums like StackExchange and Quora
high-quality contrastive finetuning on curated paired data, e.g. QA from web searches
after retrieving results, a reranker model that takes in both the inputs and the query can be used to quickly improve performance
key tricks to improve performance
training-time
instruction/task conditioning: prompt or prefixes like search query, search document, classification, clustering before embedding so model knows how to customize the embedding
synthetic data from LLMs: generate tuples of (task, query, positive, hard negative) for contrastive training, especially crafting good hard negatives
distillation from more compute-intensive model: e.g. cross-encoder to bi-encoder or post-reranker to before reranker
quantization-aware training
MoE training
sparse representation learning (e.g. UHD-BERT (jang…seo, 2021))
joint learning with index
prior work: query expansion, term dependency model (e.g. tf-idf), topic model, translation model
matryoshka representation learning - apply the contrastive loss simultaneously at dims 256, 512, 1024, 2048, etc so users can truncate to tradeoff acc for storage/speed
tailoring to specialized domains (e.g. medical, finance)
sharing embedding spaces across different model sizes (like in voyage-4) so different sizes can be used for embedding/querying
same backbone across modalities (like in voyage-3.5-multimodal) so that inputs aren’t biased towards any one modality
minor tricks: model souping / checkpoint merging on different task mixtures, loss balancing across tasks, curriculum over data quality stages, long-context extensions
document embedding-time
contextualized chunking - generate chunk embeddings for multiple chunks in one forward pass so they have context (could even aggregate context across chunks)
query inference-time
query expansion & reweighting
hybrid retrieval, combining with BM-25
reranking with a cross-encoder for topk results
Losses#
Both losses pull a query toward its positive and away from negatives. InfoNCE normalizes over every pair in the batch, which is why batch size matters; the sigmoid loss scores each pair on its own.
\(\mathcal{L}_{\text{InfoNCE}} = -\,\mathbb{E}\left[\log\frac{\textcolor{var(--nb-c-green)}{\exp\!\left(\operatorname{sim}(\mathbf{z}_i,\mathbf{z}_i^{+})/\textcolor{var(--nb-c-orange)}{\tau}\right)}}{\textcolor{var(--nb-c-purple)}{\sum_{j=0}^{N}\exp\!\left(\operatorname{sim}(\mathbf{z}_i,\mathbf{z}_j)/\textcolor{var(--nb-c-orange)}{\tau}\right)}}\right]\quad\textcolor{var(--nb-c-green)}{\text{positive pair}},\;\textcolor{var(--nb-c-purple)}{\text{all pairs (norm.)}},\;\textcolor{var(--nb-c-orange)}{\tau=\text{temperature}}\)
large batch sizes are important, can speed up computation with gradcache (gao et al. 2021) (computes loss wrt embs, then backprops through whole computation different examples at at time)
low temp. signals “focus on the hardest cases” while high temp says “treat all negatives equally”
note: this is the same as cross-entropy loss using the exp(similarity score) as the probability
this is what is used in CLIP, SimCLR, most popular
issue: can be computationally annoying to have large batch sizes / compute the denominator
\(L_{BCE} = -\mathbb{E} \Big[\, {\color{var(--nb-c-green)}y_{ij}}\log\sigma\big({\color{var(--nb-c-green)}t} \cdot {\color{var(--nb-c-purple)}\text{sim}(z_i, z_j)} + {\color{var(--nb-c-orange)}b}\big) + (1-{\color{var(--nb-c-green)}y_{ij}})\log\big(1-\sigma({\color{var(--nb-c-green)}t} \cdot {\color{var(--nb-c-purple)}\text{sim}(z_i, z_j)} + {\color{var(--nb-c-orange)}b})\big) \,\Big]\) Where: - \(\color{var(--nb-c-green)}y_{ij}\) = label (1 if true positive pair, 0 otherwise) and \(\color{var(--nb-c-green)}t\) = learnable temperature (scale) - \(\color{var(--nb-c-orange)}b\) = learnable bias
can be easier to compute because it doesn’t require large batches / normalization
easier to integrate in graded information, not just pos/neg (infoNCE sturggles because we don’t usually have graded labels across examples in the batch; if you did, could use them directly)
used in SigLIP and more
Proxy-NCA (movshovitz-attias et al. 2017) generalizes this by learning a proxy embedding per class and comparing samples to proxies, sidestepping the combinatorial explosion of pair/triplet sampling
Top-performing models#
Roughly in historical order: simple baselines, bi-encoders like SBERT, contrastive pre-training with synthetic data and instructions, then models initialized from a pre-trained LLM. Query expansion, rerankers and contextualized chunking sit on top of any of these.
Can monitor model popularity via openrouter and some evals at artificial analysis index
baseline simple models
BM25 - uses TF-IDF based on word counts and document frequences
Simple but Tough-to-Beat Baseline for Sentence Embeddings (arora, liang & ma, 2017)
average word embeddings in a sentence, downweighting words by their frequency
to remove the “common background direction”, compute the top pca component from many sentence embeddings then remove that direction
early models just trained with bi-encoders, e.g. SBERT=Sentence BERT (reimers & gurevych, 2019), SimCSE (gao, yao & chen, 2021)
PromptBERT (jiang…furu wei…zhang, 2022):
This sentence: “ [text] ” means [MASK]then use the embedding of the mask token - this prevents how all raw embeddings have similar cosine similaritiesScaling Sentence Embeddings with LLMs (jiang, …, zhuang, 2023):
This sentence: “ [text] ” means in one word:then use the embedding of the final token
next era of models started using contrastive pre-training, e.g. E5 (wang…wei, 2022), GTE (li…zhang, 2023), and BGE (github)
this era included instruction-conditioned embeddings, e.g. Instructor (su, …, smith, zettlemoyer, yu, 2022)
synthetic data became important here, e.g. Promptagator (dai…wei chang, 2022) and Gecko (lee…naim, 2024)
Nomic Embed (nussbaum, morris, duderstadt, & mulyar, 2024), (blog post)
Jina Embeddings 2 (gunther…xiao, 2024) - achieves long context (8192 tokens)
next, models initialized using a pre-trained LLM, e.g. E5-mistral-instruct (wang…wei, 2023), SGPT (muennighoff, 2022)
during post-training, remove attention masking so stuff is bidirectional, e.g. NV-Embed (lee…ping, 2024), LLM2Vec (behnamghader…reddy, 2024)
Nemotron-3-Embed (blog post, 2026) - 3 sizes: 8B (BF16), 1B (BF16), 1B (NVFP4), all available with very permissive
openmdw-1.1license8B model is adapted from Ministral-3-8B-Instruct-2512 (mistral, jan 2026)
1B model is adapted in two stages, first post-training Ministral-3-3B-Instruct-2512, then distilling it to 2B and posttraining, then distilling it to 1B and posttraining
query inference-time expansions
query2doc expansion
HyDE (gao…callan, 2022) - at inference time, generate synthetic doc from query + instruction & find match for that doc
multi-query fusion
InPars (bonifacio…nogueira, 2022) – generate questions with GPT-3; retrieve with BM25
retrieve based on multiple paraphrases and then average their reciprocal ranks to get the final reciprocal ranks
doc2query (noguiera, … cho, 2019) – train passage-to-query model on MS MARCO then retrieve with BM-25
Iterative Query Expansion with Retrieval-Grounded Relevance Feedback (bigdeli…bagheri, 2026) - at inference time, expand query (with LLM), retrieve docs for expanded query, measure similarity to original query, then re-expand and repeat (with LLM given context)
Adaptive Re-Ranking (genc, korukluoglu & allan, 2026) - sends each query to the cheapest effective re-ranking strategy, cutting latency by avoiding heavy cross-encoders on simple queries
distilling query expansions during training time
SoftQE (pimpalkhute et al., 2024) - trains the query encoder to match embeddings of LLM-expanded queries
ExpandR (yao et al., 2025) - jointly trains the retriever on LLM expansions while aligning the LLM with DPO
CAPSTONE (he et al., 2023) - moves expansion to the document side with curriculum sampling, so all generation cost is paid at indexing rather than query time
Retrieval-Feedback Distillation + Preference Alignment (li & zhou, 2026) - Transfers retrieval-friendly expansion behavior from a teacher LLM to a compact student via retrieval feedback
AQE (yang et al., 2025) - finetune small LLM to generate retrieval-optimized expansions
rerankers
3 common versions: pointwise (score each document independently), pairwise (learn “A beats B”), listwise (optimize the ordering of the whole list, targeting metrics like NDCG directly)
early models like ms-marco-MiniLM were cross-encoders, people later found that prompting an LLM did well but was expensive, so these were distilled
newer models like Rank1 use reasoning for reranking
voyage rerank-2.5 (aug 2025) - includes instruction following, e.g. “Prioritize the title and ignore the abstract”
Retrieving a Set, Not Independent Passages: Set-Level Compatibility Learning for Efficient Set Exploration (song & lee, 2026) - Introduces a set-level retrieval framework for multi-hop QA that scores query–passage-set compatibility instead of ranking passages independently
jina-reranker-v3.5: An Efficient Listwise Reranker with Hybrid Attention and Self-Distillation (nasika, wang, krasakis & xiao, 2026)
contextualized chunking
voyage does this via explicitly training a model to output separate vectors for each chunk
jina does this via late chunking (embed whole doc, get embeddings for a chunk by mean pooling over its tokens)
Contextual retreival (anthropic blog post, 2024) - prepends an LLM-generated summary to every chunk before embedding
pplx-embed-v2-context-9b-preview (perplexity & turbopuffer, sep 2026) (HF) - contextual (late-chunking) embedding model trained to retrieve the answer chunk plus its supporting context, rather than a single gold passage
more researchy
RAPTOR (sarthi…manning, 2024) - build hierarchical index by embedding, clustering, summarizing, and embedding the summaries
Contextual Document Embeddings (morris & rush, 2024) - embed docs conditioned on other docs (requires training to do this well)
Multimodal embeddings#
CLIP-style dual encoders came first and have known weaknesses, such as the modality gap. Newer models post-train one multimodal LLM so a screenshot or PDF page can be embedded directly; the subsections cover visual document retrieval, reasoning before embedding, and models that put text, images, video and audio in one space.
image-text starts with CLIP (openai, 2021), open-source replications like OpenCLIP (LAION/stability, 2022), and improvements like MetaCLIP (meta, 2023) and EVA-CLIP (BAAI, 2023)
SigLIP (zhai…beyer, 2023) - replace softmax InfoNCE with a pairwise sigmoid loss so each image-text pair is an independent binary problem (no batch-wide normalization → works at small batch sizes, cheaper); SigLIP 2 (tschannen…zhai, 2025) adds captioning + self-distillation + masked-prediction losses and native-resolution variants - now the default vision tower inside most VLMs (e.g. Qwen3-VL, PaliGemma)
LLM2CLIP (huang…furu wei, 2024) - swap CLIP’s text tower for a contrastively finetuned LLM to fix the 77-token limit and bag-of-words text understanding
Perception Encoder (bolya…feichtenhofer; meta, 2025) - contrastive vision-language pretraining alone yields strong general features, but the best ones live in intermediate layers and need alignment tuning to pull out
known weaknesses of dual encoders: modality gap - image and text embeddings occupy disjoint cones even after training (liang…zou, 2022); can’t embed interleaved text+image; bag-of-words behavior on compositional queries
can have many modality embeddings aligned through images ImageBind (meta, 2023) or through text LanguageBind (PKU, 2023)
audio-text analogue of CLIP: CLAP (elizalde…wang; microsoft, 2022), LAION-CLAP (wu…dubnov, 2023)
more modern multimodal embeddings are built by post-training existing large multimodal models (single backbone sees interleaved text+images, so a screenshot or PDF page is embedded directly with no OCR/ETL), e.g. VLM2Vec (salesforce/waterloo, 2024), GME (alibaba, 2024), voyage-multimodal-3 (voyage AI, 2024), jina-embeddings-v4 (jina AI, 2025), Gemini Embedding (google deepmind, 2025), Cohere Embed v4 (cohere, 2025)
precursors that framed “universal multimodal retrieval” (any-modality query → any-modality doc, instruction-conditioned): UniIR / M-BEIR benchmark (wei…chen, 2023), MagicLens (zhang…chang; google, 2024) - mines implicitly related image pairs from the same web page and has an LLM write the relation as the instruction
E5-V (BUAA/microsoft, 2024): even with a shared MLLM encoder, untuned image and text embeddings still show a modality gap; they train on text-only NLI pairs with a “summarize in one word” prompt and it transfers to images
MM-Embed (NVIDIA, 2024): MLLM retrievers exhibit modality bias (asked for an image, they retrieve text), fixed with modality-aware hard-negative mining + a continued text-only finetuning stage to keep MTEB scores
hard-negative tricks: LLaVE (lan…tang, 2025) weights in-batch negatives by hardness; UniME (gu…deng, 2025) distills from a text LLM then does hard-negative finetuning, and UniME-V2 (gu…bing, 2025) uses an MLLM-as-judge to score candidates and train against soft matching scores rather than binary pos/neg; QQMM (2025) explicitly amplifies the gradient from hard negatives in InfoNCE
keeping generative ability: VladVA (ouali…tzimiropoulos, 2024) and CAFe (yu…, 2025) add an autoregressive LM loss alongside contrastive loss so the embedder doesn’t forget how to generate
MoEMB (sep 2026) - finds one embedder trained jointly over all tasks underperforms per-task models (gradient interference or capacity), motivating sparse MoE embedders
Douyin Multimodal Embedding (chen…dou; bytedance, aug 2026) - industrial recipe: large-scale contrastive pretraining for a broad space, then a stage that recovers the fine-grained discrimination of CoT-based models without paying generation cost at serving time
visual document retrieval (embed page screenshots instead of extracted text)
DSE: Document Screenshot Embedding (ma…lin, 2024) - single-vector version
ColPali (faysse…colombo, 2024) - late interaction over VLM patch tokens: each page → ~1024 patch embeddings (128-d), scored with MaxSim against query tokens; introduced ViDoRe; skips chunking entirely
family: ColQwen2/2.5/3 (Qwen-VL backbones), ColSmol, ColModernVBERT (teiletche…, 2025) - 250M params within 0.6 nDCG of ColPali, Nemotron ColEmbed V2 (NVIDIA, 2026) - Qwen3-VL 4B/8B with bidirectional attention; projecting to 128-d keeps ~95% accuracy at 3% storage, but 1M pages still need ~180GB
jina-embeddings-v4 outputs both a 2048-d dense vector (MRL-truncatable to 128) and 128-d per-token vectors from one model, so you can trade indexing cost for precision without switching models
MetaEmbed (meta, 2025) - append a small set of learnable “meta tokens” and train so any prefix of them works as a multi-vector embedding → test-time scaling of retrieval quality vs cost (matryoshka over number of vectors)
storage is the pain point → training-free multi-vector compression via token pooling / anchor pruning (e.g. Structural Anchor Pruning (2026)), or MUVERA-style fixed-dimensional encodings that let multi-vector sets use standard ANN
visual-token efficiency for single-vector models: Magic-MM-Embedding (li…liu, 2026) reduces visual tokens before pooling
reasoning-driven embeddings - let the MLLM think before emitting the vector
UME-R1 (2025) - generate a CoT then pool; RL-trained; big gains on compositional/instruction tasks but impractical to serve online
Embed-RL (jiang…tang, 2026) - Embedder-Reasoner RL loop where the embedder supervises the reasoner so CoT traces stay aligned with embedding tasks
PLUME (he…wang, 2026) - latent (non-verbal) reasoning tokens instead of explicit CoT to recover most of the gain at bi-encoder cost
omni-modal (text + image + video + audio in one space)
Omni-Embed-Nemotron (NVIDIA, 2025), LCO-Embedding (2025) - language-centric omnimodal training on Qwen2.5-Omni
Gemini Embedding 2 (google deepmind, may 2026) - native multimodal from Gemini; arbitrary interleaved text/image/video/audio/document inputs; multi-task multi-stage contrastive training; SoTA across unimodal, cross-modal, and mixed-modal retrieval simultaneously (69.9 MTEB multilingual, 84.0 MTEB code)
jina-embeddings-v5-omni (jina, 2026) - nano (0.95B) / small (1.57B); bolts SigLIP2 vision + Whisper audio encoders onto the frozen v5 text model so text quality is bit-identical; small matches 7B omni baselines on average, video is the remaining gap
Conan-embedding-v3 (2026) - merge separately trained modality-specialist backbones; works for vision/video/doc but audio regresses because the projector was calibrated to the audio-specialist backbone (“projector drift”), fixed by re-tuning the projector with backbone frozen
Ovis-Omni-Embedding-3B - initialize from Qwen2.5-Omni Thinker (drop Talker + LM head), last-token pooling; leads MMEB-V3 aggregate
video - usually samples frames and embeds them rather than explicit temporal modeling
voyage-multimodal-3.5 (jan 2026) - videos are represented as an ordered sequence of frames and input to the model as images - every 1120 pixels of a video counts as a token, for a maximum of 32k tokens; first production video model with matryoshka dims
VLM2Vec-V2 (meng…chen, 2025) - extends VLM2Vec to videos + visual docs, introduces MMEB-V2
WAVE - unified audio-visual embeddings for audio↔video retrieva
Papers with a little trick#
Single changes to an embedding model, grouped by when they act: during pre-training (masked autoencoding), during training (one model for generation and embeddings, Matryoshka prefixes that work as smaller embeddings), after training, or at query time (repeating the input so the second copy sees all of it).
mask removal (masked autoencoder MAE)-time
DupMAE = RetroMAE v2: Duplex Masked Auto-Encoder For Pre-Training Retrieval-Oriented Language Models (xiao & liu, 2022) - add loss so that CLS token can recover the entire input and individual token embeddings can recover bag-of-words
then, use low-dim representation of both embeddings concatenated as the embedding
training-time
GritLM (meunninghoff…kiela, 2024) - train a single model that, given different instructions, can produce either generations or embeddings
Matryoshka Representation Learning (kusupati…kakade, jain, & farhadi, 2022) - in training given an embedding of full dimensionality M (e.g. 2048), learn N different distance functions for each prefix of the embedding (e.g. l2_norm(embedding[:32]), l2_norm(embedding[:64]), l2_norm(embedding[:128]), etc).
Beyond Matryoshka: Revisiting Sparse Coding for Adaptive Representation (wen…you, 2025) - instead learn sparse mask on top of original embedding
AGRAME: Any-Granularity Ranking with Multi-Vector Embeddings (reddy…potdar, 2024) - rank at varying levels of granularity while maintaining encoding at a single (coarser) level
EvoEmbedding: Evolvable Representations for Long-Context Retrieval and Agentic Memory (nie, fu, feng & shan, 2026) - maintains a continuously updated latent memory as it sequentially processes inputs, and uses it alongside the raw content to jointly generate embeddings
DREAM: Dense Retrieval Embeddings via Autoregressive Modeling (tang & yang, 2026) - instead of contrastive learning, use retriever to replace attention scores for particular heads in next-token prediction task
Relevance-Based Embeddings (shevkunov, ploskonosov & prokhorenkova, 2026) - rather than biencoder, generate embedding vector by concatenating the cross-encoder similarity of query to a list of support docs
Lightweight Fine-Tuning for Flexible Multi-Vector Compression (josef, 2026) - lightweight k-means pooling-aware fine-tuning lets ColBERT models compress vectors with no accuracy loss
AutoIndex: Learning Representation Programs for Retrieval (o’nuallain…drozdov, 2026) - autoresearch for learning how to embed using a fixed BM25 retriever
post-hoc
Your UnEmbedding Matrix is Secretly a Feature Lens for Text Embeddings (wu…yan, 2026) - project out directions for small SVs of unembedding matrix inverse (these are in the null space and where constant bias is held) and for large SVs (these are shared between everything and not helpful for embeddings)
query inference-time
EchoEmbeddings: Repetition Improves LM Embeddings (springer, kotha, fried, neubig, & raghunathan, 2024)
Feed a prompt such as “Rewrite the sentence: x, rewritten sentence: x” to the LM and pool the contextualized embeddings of the 2nd occurence of x
Datasets / benchmarks#
MTEB is the standard leaderboard but may be overfit: paraphrasing its test sets lowers scores. Newer benchmarks use private data, instructions, agentic or long-context search, and the last group lists the data used to train embedding models.
MTEB leaderboard - most common (but potentially overfitted) benchmark
MMTEB - multilingual version
mutimodal
standard: MMEB (huang…meng, 2026), MIEB: Massive Image Embedding Benchmark (xiao…muennighoff, 2025)
visual document retrieval: ViDoRe, ViDoRe v2, MIRACL-VISION
PTEB paper (frank & afli, 2025) finds that paraphrasing MTEB test sets substantially lowers scores (suggesting overfitting)
SAGE: A Realistic Benchmark for Semantic Understanding (goel, lee & ramchandran, 2025) - evaluates retreival robustness under adversarial and noisy conditions
AIR-Bench: Automated Heterogeneous Information Retrieval Benchmark (chen…liu, 2024) - refreshable llm-generated eval data
Older: BEIR benchmark (part of MTEB)
newer retrieval benchmarks
RTEB - retrieval only benchmark of 48 datasets, with 28 private datasets and 26 code-retrieval datasets; newer and hopes to avoid MMTEB overfitting
OBLIQ-Bench: Exposing Overlooked Bottlenecks in Modern Retrievers with Latent and Implicit Queries (tchuindjo, shah & khattab, 2026)
EnterpriseRAG-Bench: A RAG Benchmark for Company Internal Knowledge (sun…butler, 2026)
MAIR (Massive Instructed Retrieval) benchmark (sun et al. 2024) - dataset for instruction-informed retrieval
BERRI: Task-aware Retrieval with Instructions (asai…riedel, hajishirzi, & yih, 2023)
FollowIR (weller…soldaini, 2024)
agentic search
BrowseComp-Plus (chen…lin, 2025) - evaluates deep research when searching a fixed corpus
extends BrowseComp (wei…glaese, 2025) - uses web search to evaluate QA
InfoDeepSeek: Benchmarking Agentic Information Seeking for RAG (xi…yu, 2025)
Long context datasets
Jina Long Context Benchmark (günther et al. 2023)
Misc minor
TREC-RAG dataset
Instructor eval: Billboard, Prompt retrieval
Training datasets
Nomic 235M curated text pairs (mostly filtered from here)
Followed by supervised contrastive fine-tuning on datasets like MSMarco, NQ, NLI, HotpotQA, Fever, WikiAnswers, etc.
MEDI (from Instructor paper): combines 300 datasets from Super-NaturalInstructions with 30 datasets from existing collections designed for embedding training
Agentic search#
Here retrieval is one tool in a loop: an agent plans searches, reads results and searches again. Two of these papers find that grep over the raw corpus does as well as or better than vector retrieval here.
Agentic search - agent actively plans, executes, and iterates on searches to answer a query, rather than just running a single keyword lookup and handing back results
FastContext: Training Efficient Repository Explorer for Coding Agents (zhang…fu, 2026) - exploration models from 4B-30B
Search-R1: Training LLMs to Reason and Leverage Search Engines with RL (jin…han, 2025)
Beyond Semantic Similarity: Rethinking Retrieval for Agentic Search via Direct Corpus Interaction (li…zhang, 2026) - agent searches the raw corpus directly using
grep,find,bash, shell pipelines rather than embedding modelsChroma Context-1: Training a Self-Editing Search Agent (bashir, hong, jiang, & shi, 2026)
MemReranker: Reasoning-Aware Reranking for Agent Memory Retrieval (li…li, 2026)
Are We Ready For An Agent-Native Memory System? (zhou…wu, 2026)
MemoryBank: Enhancing LLMs with Long-Term Memory (zhong…wang, 2023) - maintains experiences as timestamped memory streams and periodically summarizes them into higher-level reflections
Superintelligent Retrieval Agent: The Next Frontier of Information Retrieval (yang, ma, chen & shrivastava, 2026)
asks which terms are likely to separate the desired evidence from corpus-level confusers
doc side: LLM enriches each document offline with missing search vocabulary
query side: predicts evidence vocabulary omitted by the query & document-frequency statistics as a tool call to filter proposed terms that are absent, overly common, or unlikely to create retrieval margin
final retrieval step is weighted BM25 call combining the original query with the validated expansion
GrepSeek: Training Search Agents for Direct Corpus Interaction (salemi…zamani, 2026) - trains a compact search agent to find, filter, and compose evidence from large text corpora
Is Grep All You Need? How Agent Harnesses Reshape Agentic Search (sen…subbiah, 2026) - grep generally outperforms vector retrieval in agentic RAG workflows, but overall accuracy depends heavily on agent harness
MemEx: A Programmable Scratchpad for LLM Agents (databricks research team, 2026) - improves token efficiency with a wrapper layer over tools, that stores objects in python rather than text every time
Adapting Embedding Models for Agent Capability Retrieval (chen…xu, 2026) - fnetunes 3 retrieval models on synthetic capability-profile data
https://jbarrow.ai/2026-06-12-searching-fast-and-slow/:
(ref)

Searching embeddings (approximate nearest neighbor)#
Exact nearest-neighbor search compares the query with every stored vector. Each method below avoids that by building an index once (left figure) and searching only a small part of it per query (right figure). Product quantization is different: it makes each comparison cheaper instead of making fewer of them.
locality-sensitive hashing (outdated) is a fuzzy hashing technique that hashes similar input items into the same “buckets” with high probability
idea is to project vector along random dimensions to create buckets, and then match those buckets before searching the rest
issue is that the number of dimensions needed to get good performance can quickly grow, obviating the benefit
hash collisions are maximized, rather than minimized as they are in dictionaries
finding embeddings via DNNs is a special case of this (e.g. might call it “semantic hashing”)
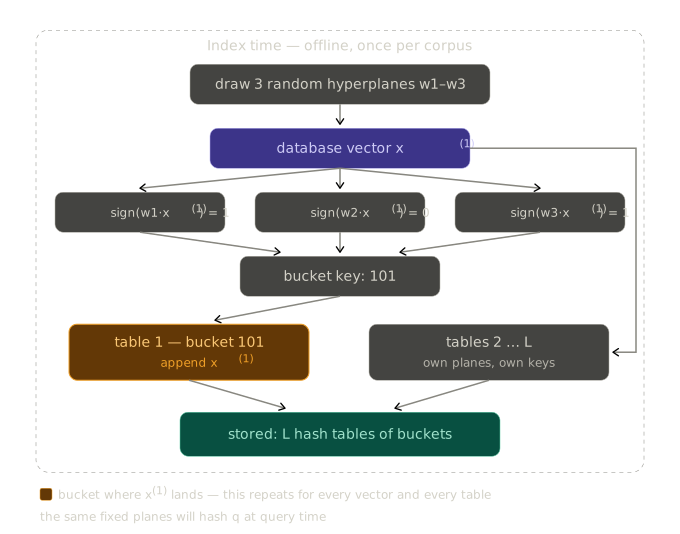
Fig. 151 Figure 2. Locality-sensitive hashing, index time: each vector is hashed by which side of a few random hyperplanes it falls on, and the sign bits pick its bucket. Several tables repeat this with different planes.#
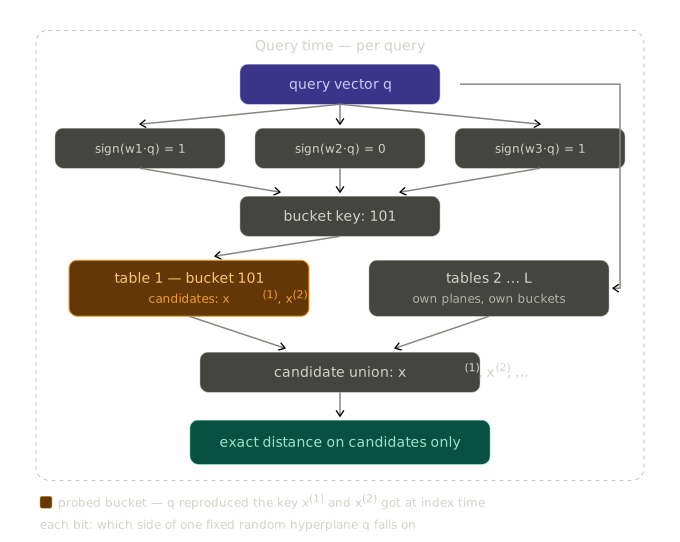
Fig. 152 Figure 3. Locality-sensitive hashing, query time: the query is hashed with the same planes and only the vectors in its buckets are compared exactly.#
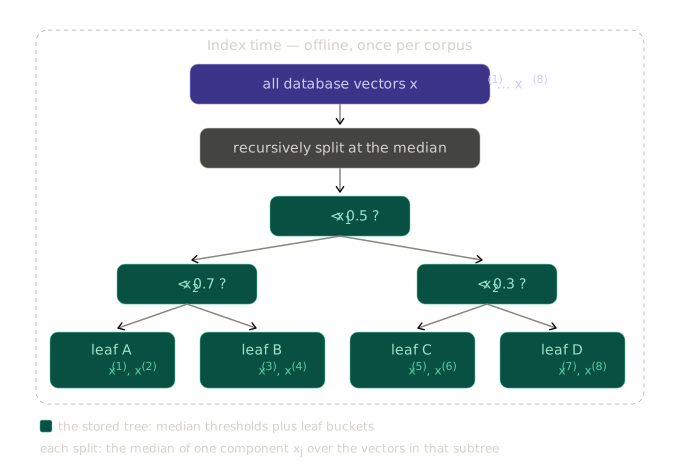
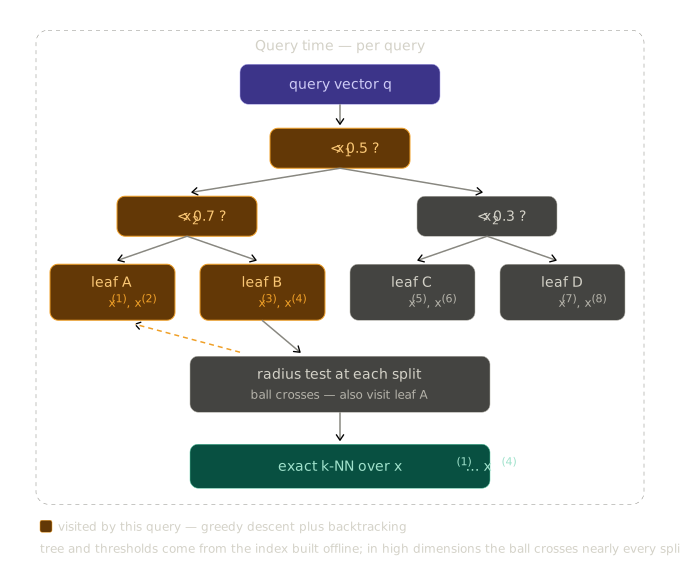
k-d (k-dimensional) tree
balanced binary tree over data with arbitrary dimensions, where each node splits one dim
at inference time, go to leaf and then search all neighbors of the leaf by going back up it
annoy optimized this to instead use a forest of random trees and to do data-driven splitting (take 2 random points and split on the direction between them) rather than the median of a single dim
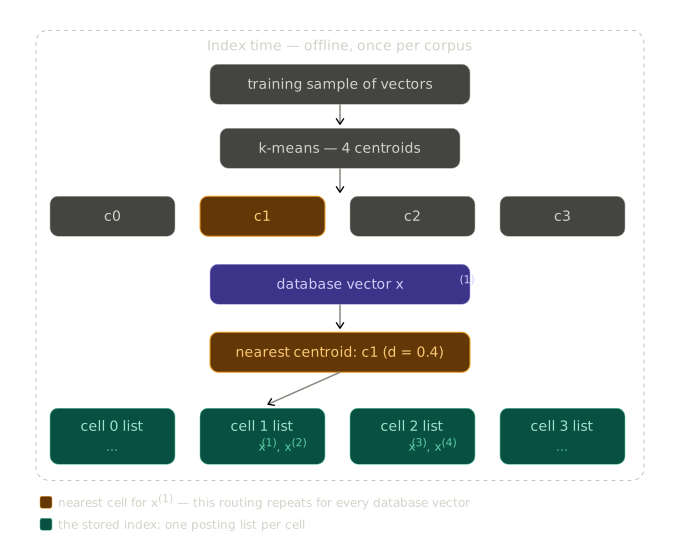
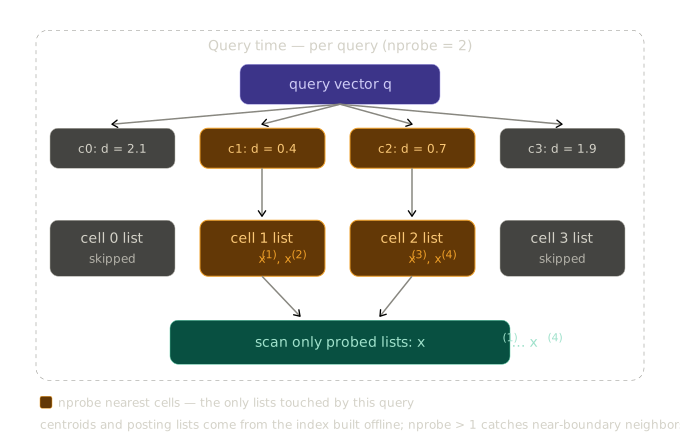
inverted file (IVF) - k-means the embeddings into clusters, then at inference first search the cluster centers before searching within the top clusters
to improve performance, add neighbors into mutiple clusters
product quantization (jegou et al. 2011) - this speeds up the vector comparison time (different from everything else)
separate vector into subvectors (e.g. first half, second half), run k-means for each subvector, then replace the subvector with the index of its closest center mean
at inference time, split the query into the same subvectors, and pre-compute the squared distance to each of the center means for each subvector
then, for each vector, rather than doing the dot-product, just look up the pre-computed distances for each subvector (add them together to get the squared distance for the whole vector)
note: splitting vectors and clustering struggles if there are lots of correlations between different subvector parts, one fix for this is Optimized PQ (OPQ), which learns a rotation to apply before splitting so the variance is balanced and decorrelated across subspaces
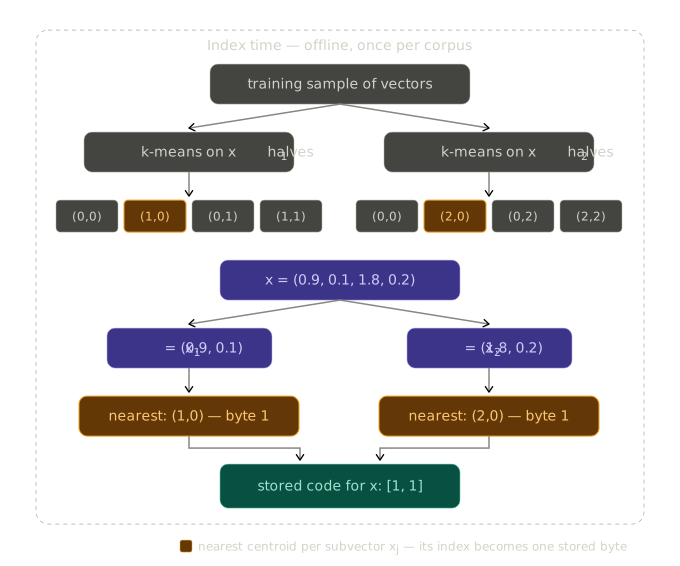
Fig. 157 Figure 8. Product quantization, index time: each vector is split into subvectors, and each subvector is replaced by the index of its nearest centroid in that subspace’s codebook.#
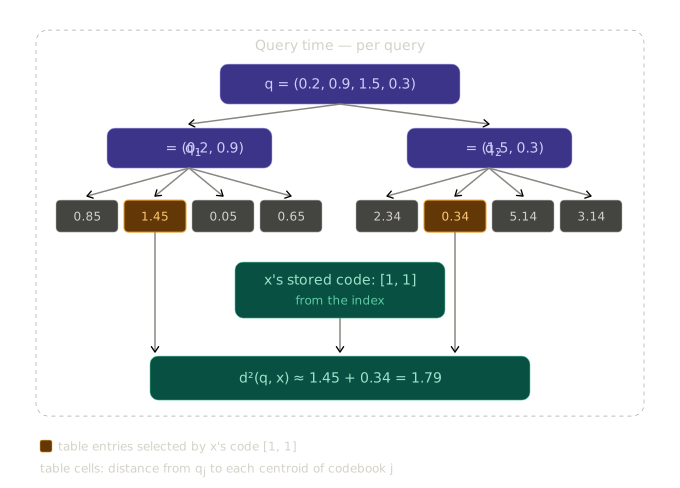
Fig. 158 Figure 9. Product quantization, query time: distances from each query subvector to every centroid are precomputed once; the distance to any stored vector is then a sum of table lookups.#
HNSW (malkov & yashunin, 2016) - Hierarchical Navigable Small World graphs (most popular modern system including Lucene, pgvector, Qdrant, Weaviate, Milvus, Pinecone’s early stack for medium-large scale <10M vectors)
idea is to build a proximity graph over the vectors, and answer queries with greedy best-first traversal - start somewhere, repeatedly hop to the neighbor closest to the query, and search its neighbors
hierarchy: does search at a higher layer, then drops to neighbors in lower layer which are more refined
edge-selection at insert time
note: naive graph of neighbors doesn’t work because it’s very hard to find a new neighbor if you search in the wrong place; instead NSW inserts points in random order and connects each to its M nearest at insertion time (this leaves long-range edges from the early added nodes)
supports incremental inserts (although build and insert are both expensive)
delete is a pain
requires a lot of RAM (rather than disk access)
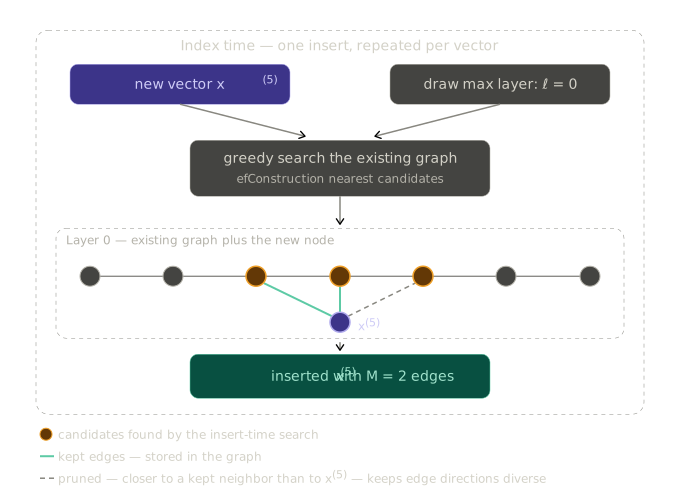
Fig. 159 Figure 10. HNSW, inserting one vector: it draws a random top layer, a greedy search finds candidate neighbors, and pruning drops a candidate that is closer to an already-kept neighbor than to the new vector.#
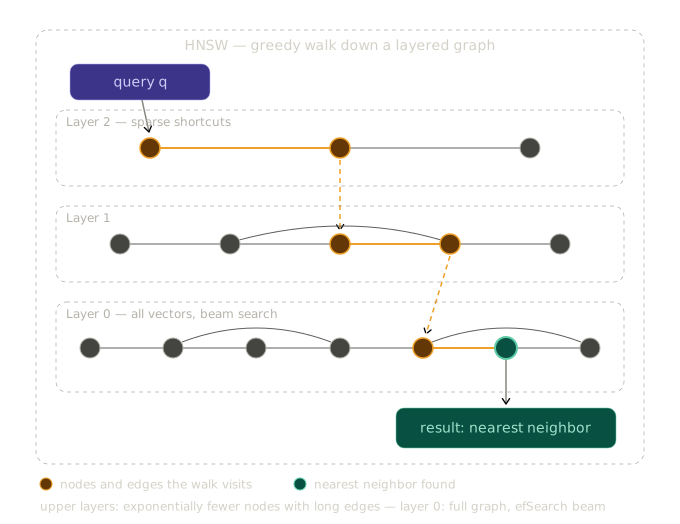
Fig. 160 Figure 11. HNSW, query time: the search starts on the sparse top layer, hops greedily toward the query, and drops a layer each time it can’t get closer.#
moving more stuff to disk instead of RAM (default for very large scale, 100M+ vectors)
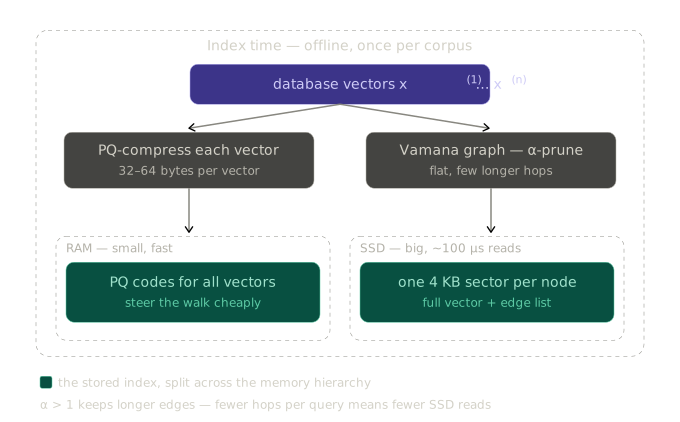
DiskANN (subramanya…harsha vardhan simhadri, 2019; CMU, UT austin, & MSR) - store the full-precision vectors and graph on SSD, keep only PQ-compressed vectors in RAM
introduce Vamana graph construction algorithm to produces fewer, longer-range hops in the graph to minimize SSD round-trips
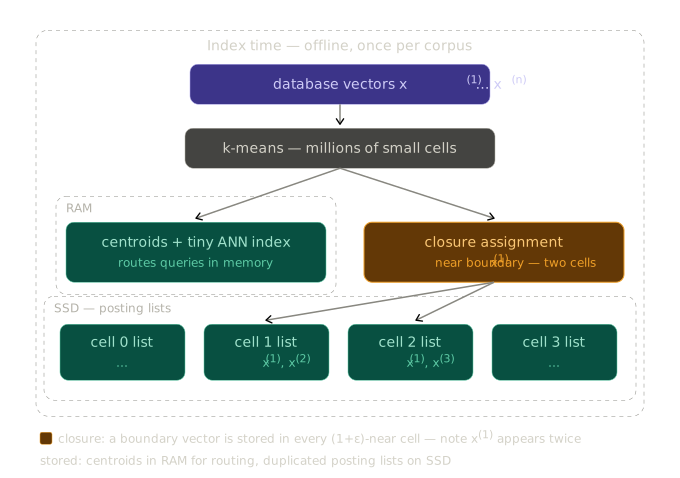
SPANN (chen…wang, 2021) - same thing but for IVF cluster approach rather than PQ
other considerations
modern libraries often deal carefully with quantization and GPU usability
building compressions/graphs that are filter-aware, e.g. user issues queries like “nearest neighbors WHERE tenant=X AND date>Y.” should not break the search
libraries:
Library |
What it is |
Methods it connects to |
|---|---|---|
Faiss (Meta) |
The field’s reference library, CPU and GPU. Nearly every classical index type, composable (e.g. IVF coarse layer + PQ codes + rescoring). |
Brute force, IVF, PQ/OPQ, IVF-PQ (asymmetric distance computation), HNSW, scalar/binary quantization |
hnswlib (Malkov) |
The canonical lightweight HNSW implementation by the paper’s author; embedded inside many engines. Sibling research library: nmslib (original NSW). |
HNSW exactly — M, efConstruction, efSearch, diversity pruning |
ScaNN (Google) |
Partitioning plus anisotropic quantization — the PQ loss reshaped to penalize ranking-relevant error. |
IVF + PQ with a smarter estimator (“train the index for the metric”) |
DiskANN (Microsoft) |
Vamana graphs served from SSD; Fresh (streaming) and Filtered variants. |
DiskANN — α-prune build, PQ-steered beam search, packed SSD sector reads |
SPTAG (Microsoft) |
Tree-plus-graph library; home of the SPANN design used in Bing-scale search. |
SPANN — in-RAM centroid routing, closure assignment for boundary vectors |
Annoy (Spotify) |
Random-projection tree forest; mmap-friendly, immutable, simple. Largely legacy now but still deployed. |
The tree lineage — the KD-tree’s randomized, ensembled descendant |
Research-grade LSH (cross-polytope and hyperplane families) with multi-probe. |
LSH, with the modern hash families and fewer tables |
|
cuVS (NVIDIA) |
GPU-native ANN: CAGRA graph build and search, GPU IVF-PQ; build speedups that change reindexing economics. |
Graph traversal + IVF-PQ, rebuilt for massive parallelism |
Engine |
What it is |
Methods it connects to |
|---|---|---|
Lucene (→ Elasticsearch, OpenSearch, MongoDB Atlas) |
Segment-based search engine whose vector support underlies Elasticsearch, OpenSearch, and Atlas Vector Search; immutable segments sidestep graph deletes. |
HNSW per segment + int8/binary quantization with exact rescoring |
Postgres extension; vectors as a column type with SQL filtering and joins. |
HNSW, IVF (IVFFlat), and exact brute-force scans |
|
Distributed vector database; its Knowhere engine wraps multiple index families behind one API. |
Nearly everything: Faiss indexes, HNSW, DiskANN, GPU variants |
|
Rust vector database emphasizing payload filtering and compression. |
HNSW + scalar/binary quantization; filter-aware traversal |
|
Go vector database with hybrid (BM25 + vector) search built in. |
Custom HNSW with PQ/binary compression and rescoring |
Notes: popularity and internals shift quickly — verify against ann-benchmarks.com before depending on any of these. The engines section contains no new algorithms: each is HNSW-or-IVF plus quantization plus the operational layer (filtering, replication, segments, hybrid search).
foundations of vector retrieval book (bruch, 2024)
similarity metrics
Anisotropy Decides Cosine vs. Rank Metrics for Text Embeddings (parupudi, 2026) - choice of similarity metric depends on embedding geometry: cosine is best when variance spreads evenly & L1-type metrics win when variance concentrates into a few directions
euclidean, cosine, and dot product are most common
when embeddings normalized to have norm 1, euclidean and dot product yield the same rankings because \(\Vert q - d\Vert ^2 = \Vert q\Vert ^2 + \Vert d\Vert ^2 - 2(q \cdot d) = 2 - 2(q \cdot d)\)
Explainable embeddings#
Most of these build an embedding whose dimensions mean something, usually answers an LLM gives to yes/no questions about the text. Others explain why two inputs were judged similar.
QA-Emb: Crafting Interpretable Embeddings by Asking LLMs Questions (benara…gao, 2024) - use yes/no questions to extract embeddings from text
A General Framework for Producing Interpretable Semantic Text Embeddings (sun…yu, 2024) - extend QA-Emb to systematically generate highly discriminative, low cognitive load yes/no questions
PromptReps: Prompting LLMs to Generate Dense and Sparse Representations for Zero-Shot Document Retrieval (zhuang…zuccon, 2024)
InBedder: Answer is All You Need: Instruction-following Text Embedding via Answering the Question (peng…jingbo shang, 2024)
embeddings consist of answers to questions
answer models are finetuned on QA datasets
questions are given ahead of time
Meta-Task Prompting Elicits Embedding from LLMs (lei…yates, 2024) - ask a few pre-canned templates e.g. “Categorize into one of these categories ___” and look at logits for the outputs as an embedding
Learning Interpretable Style Embeddings via Prompting LLMs (patel, rao, kothary, mckeown, & callison-burch, 2023)
CHiLL: Zero-shot Custom Interpretable Feature Extraction from Clinical Notes with LLMs (mcinerney…wallace, 2023)
extract interpretable feature (e.g. “Does this patient have a chronic illness?”) and use in a linear model (use Flan-T5)
example features: 10 ICD codes + (1) Does the patient have a chronic illness? (2) Is the condition life-threatening?
Concept Induction: Analyzing Unstructured Text with High-Level Concepts Using LLooM (lam…bernstein, 2024)
Explain via Any Concept: Concept Bottleneck Model with Open Vocabulary Concepts (tan, zhou, & chen, 2024)
BC-LLM: Bayesian Concept Bottleneck Models with LLM Priors (feng…tan, 2024)
Learning Interpretable Concept-Based Models with Human Feedback (lage & doshi-velez, 2020)
Interpretable-by-Design Text Understanding with Iteratively Generated Concept Bottleneck (ludan…callison-burch, 2023)
Programmatic Representation Learning with LMs (poesia & sampaio, 2025) - build decision trees on llm-extracted features
HypotheSAEs (movva…pierson, 2025)
Evaluating scientific theories as predictive models in language neuroscience (singh…huth, 2025)
Bridging Brains and Concepts: Interpretable Visual Decoding from fMRI with Semantic Bottlenecks (cammarota, ferrante & toschi, 2025)
Disentangling Superpositions: Interpretable Brain Encoding Model with Sparse Concept Atoms (zeng & gallant, 2025)
apply sparse coding to word embeddings (e.g. eng1000) before fitting linear encoding models to mitigate feature correlations
normalize word embeddings before fitting so that highly frequent words (which are closer to the origin) do not end up with the same dictionary codes simply because of their frequency
Interpreting Brain Responses to Language with Sparse Features from LMs (lepori, kay & tuckute, 2026)
Box Embeddings: An open-source library for representation learning using geometric structures (chheda…mccallum, 2021) - allow for learning non-symmetric relations (e.g. entailment)
Bridging Continuous and Discrete Spaces: Interpretable Sentence Representation Learning via Compositional Operations (huang…yu, 2023) - learn interpretable compositional operations, which helps with similarities for compositional tasks
Dense Retrievers Know More Than They Can Express (mixedbread ai blog post, 2026) - use SAE followed by BM25 on SAE embeddings
multimodal
SPLICE: Interpreting CLIP with Sparse Linear Concept Embeddings (bhalla…lakkaraju, 2024)
given CLIP, build an embedding concept dictionary by taking text embeddings of a bunch of individual semantic words
given a new image, get its image embedding and then decompose it into a sparse, nonnegative combination of the concept dictionary (this makes it interpretable)
Sparse CLIP: Co-Optimizing Interpretability and Performance in Contrastive Learning (qin…scherer, 2026) - post-train CLIP to use sparse features
Computer-vision focused
Axiomatic Explanations for Visual Search, Retrieval, and Similarity Learning (hamilton, lundberg…freeman, 2021) - add in “second-order” methods that look at similarities between different image features in the 2 images being compared
Why do These Match? Explaining the Behavior of Image Similarity Models (plummer…saenko, forsyth, 2020) - generate saliency map + with an attribute based on the salient region
Towards Visually Explaining Similarity Models (zheng…wu, 2020) - similarity of cnn embeddings
Interpretable entity representations through large-scale typing (onoe & durrett, 2020) - embedding is interpretable predictions for different entities
Explaining similarity with different outputs
Analogies and Feature Attributions for Model Agnostic Explanation of Similarity Learners (ramamurthy…tariq, 2022) - returned explanation is an analogy (pair from the training set) rather than a saliency map
Sim2Word: Explaining Similarity with Representative Attribute Words via Counterfactual Explanations (chen…cao, 2023) - give both saliency map + counterfactual explanation
Retrieval augmented generation (RAG)#
The table from the RAG perspective paper sorts systems by what they retrieve (chunks, tokens, phrases), where it enters the model, how often retrieval happens, and whether the retriever and LM are trained jointly.
RAG perspective paper (asai, zhong, chen, koh, zettlemoyer, hajishirzi, & yih, 2024)
Granularity
Incorporation
Frequency
Training
Data order
DrQA
Chunks
Input
One-time
Independent
\(O\left(10^9\right)\)
REALM, RAG, ATLAS
Chunks
Input
One-time
Joint
\(O\left(10^9\right)\)
RALM, REPLUG
Chunks
Input
Every \(k\) tokens, One-time
Independent*
\(O\left(10^9\right)\)
Active-Retriever, Self-RAG
Chunks
Input
Adaptive
Independent*, Sequential
\(O\left(10^9\right)\)
RETRO, InstructRetro
Chunks
Intermediate
Every \(k\) tokens
Sequential
\(O\left(10^{12}\right)\)
kNN LM, TRIME
Tokens
Output
Every token
Independent*, Joint
\(O\left(10^9\right)\)
NPM, Copy Generator
Phrases
Output
Every phrase
Joint
\(O\left(10^9\right)\)
SPALM, Adaptive kNN
Tokens
Output
Adaptive
Independent*, Joint
\(O\left(10^9\right)\)
RAGGED: Towards Informed Design of Retrieval Augmented Generation Systems (hsia…neubig, 2024) - gives benchmark of multi-hop QA questions for evaluating RAG systems holistically
https://pageindex.ai/ - popular system that replaces vector-based rag with table-of-contents based search for docs that are already well organized
Seven Failure Points When Engineering a Retrieval Augmented Generation System (barnet…abdelrazek, 2024)
dynamic systems
Active RAG (jiang…neubig, 2023) - propose FLARE, which iteratively uses a prediction of the upcoming sentence to anticipate future content, which is then utilized as a query to retrieve relevant documents to regenerate the sentence if it contains low-confidence tokens
Self-RAG: Learning to Retrieve, Generate, and Critique through Self-Reflection (asai…hajishirzi, 2023) - train an LM that adaptively retrieves passages on-demand, and generates and reflects on retrieved passages and its own generations using special tokens, called reflection token
Infer–Retrieve–Rank: In-Context Learning for Extreme Multi-Label Classification (d’oosterlinck, …, potts, 2024)
Infer: an LM processes the input document and guesses a set of applicable terms
Retrieve: a retriever relates each predicted term to the actual label space
Rank: Finally, an LM is used to rerank retrieved labels
Adaptive-RAG: Learning to Adapt Retrieval-Augmented LLMs through Question Complexity (jeong…park, 2024) - dynamically selects the most suitable retrieval-augmented strategy based on the predicted complexity level of input query
From Local to Global: A Graph RAG Approach to Query-Focused Summarization (edge…larson, 2024) - build and summarize a graph of documents to be used at query time for summarizing docs
Original papers
RAG for Knowledge-Intensive NLP Tasks (lewis, perez, …kiela, 2020) - introduce idea of end-to-end RAG
k-nearest neighbors LM (khandelwal…zettlemoyer, lewis, 2020)
REALM (guu, …, chang, 2020) - retrieves document chunks from corpus and adds them to context, for open-domain QA
early systems
DrQA (chen, weston, bordes 2017)
ORQA (lee…toutanova, 2019)
retrieval-augmented in-context learning (put retrieved info into context, or something very similar)
RETRO (deepmind, 2022) - nearest neighbors to model’s input are retrieved, encoded, and conditioned on with chunked cross-attention
Decomposed prompting (khot et al., 2022) - decompose tasks via prompting which are delegated to a shared library of prompting-based LLMs dedicated to these sub-tasks
retrieval-in-context approach (shi, min et al. 2023; ram…shoham, 2023) - retrieve docs and preprend to the context
LLM-Augmenter (peng, galley…gao, 2023) - (1) consolidates evidence from external knowledge for the LLM to generate responses grounded in evidence, and (2) revising LLM’s (candidate) responses using automated feedback
DRAGON: Diverse Augmentation Towards Generalizable Dense Retrieval (Lin et al 2023)
Knowledgeable Prompt-tuning (hu et al. 2021) - add knowledge-base info into the prompt search
Atlas: Few-shot Learning with Retrieval Augmented LMs (meta, 2022)
GRIT: Generative Representational Instruction Tuning (muennighoff et al 2024) - train same model for text generation and retrieval tasks
Fine-grained Hallucination Detection and Editing for LMs (mishra, …, hajishirzi, 2024) - train a retrieval-augmented LM to correct fine-grained hallucinations
RAG can even outperform LMs fine-tuned on the downstream domain data on QA (Ovadia et al., 2023; Gupta et al., 2024)
Different ideas
Transformer Memory as a Differentiable Search Index (tay at al 2022) - Same model learns to encode documents and find closest search index (rather than retrieving with maximal inner product search)
Self-Retrieval: Building an Information Retrieval System with One LLM (tang…li, 2024) - LLM learns to generate retrieved document from query
xRAG: Extreme Context Compression for RAG with One Token (cheng…furu wei…zhao, 2024)
interpretable RAG
PlugMem: A Task-Agnostic Plugin Memory Module for LLM Agents (ke yang, …, galley, wang, gao, han, & zhai, 2026) - optimize performance vs num tokens in memory
T-Retriever: Tree-based Hierarchical Retrieval Augmented Generation for Textual Graphs (wei…chen, 2026)
Universal representations#
Evidence that different models learn similar representations, from shared SAE features and neurons to translating embeddings between models without paired data.
Universal Sparse Autoencoders: Interpretable Cross-Model Concept Alignment (thasarathan…derpanis, 2025)
Sparse Crosscoders for Cross-Layer Features and Model Diffing (anthropic blog post, 2024) - learn SAE across different layers of same model
Quantifying Feature Space Universality Across LLMs via Sparse Autoencoders (lan…barez, 2025)
From Tokens to Thoughts: How LLMs and Humans Trade Compression for Meaning (shani, jurafsky, lecun, & shwartz-ziv, 2025)
LLM-derived clusters significantly align with human-defined conceptual categories but only modest alignment with human-perceived fine-grained semantic distinctions
LLMs demonstrate markedly superior information-theoretic efficiency in their conceptual representations compared to human conceptual structures
The Platonic Representation Hypothesis (huh, cheung, wang, & isola, 2024)
vec2vec (jha, zhang, shmatikov, & morris, 2025) - use cyclegan-style approach to translate embeddings from one space to another (without paired samples)
The Universal Weight Subspace Hypothesis (kaushik…yuille, 2025)
Anatomy of a ML Ecosystem: 2 Million Models on Hugging Face (laufer, oderinwale & kleinberg, 2025)
Canonicalizing Multimodal Contrastive Representation Learning (gupta…garg, 2026)
Shared Geometry As A Rosetta Stone: Cross-Modal Alignment Without Paired Data (schnaus…isola, 2026)
Rosetta Neurons: Mining the Common Units in a Model Zoo (dravid, …, efros, shocher, 2023)
Multimodal Neurons in Pretrained Text-Only Transformers (schwettmann…torralba, 2023)
Interpreting CLIP’s Image Representation via Text-Based Decomposition (gandelsman, efros, & steinhardt, 2023)
Universal Neurons in GPT2 LMs (gurnee…nanda, & bertsimas, 2024) - study the universality of neurons across GPT2 models trained from different initial random seeds
Text-To-Concept (and Back) via Cross-Model Alignment (moayeri…feizi, 2023) - given a new image encoder, if we want to align it to a text encoder, we can just learn a linear transformation from image embeddings to CLIP image embeddings and use the CLIP text encoder
Embedding inversions#
An embedding can leak its input: these methods recover the text from an embedding, or the prompt from a model’s outputs. The last papers give theoretical limits on what single-vector retrieval can represent.
Generative Embedding Inversion Attack to Recover the Whole Sentence (li…song, 2023) - train projection to LM jointly to reconstruct input
Information Leakage from Embedding in LLMs (wan…wang, 2024)
base embed inversion - directly pass hidden states to the LM head for generation
hotmap embed inversion - find input which yields embedding with greatest cosine similarity
embed parrot - learn a linear mapping to embedding states that is then
vec2text (morris et al. 2023) - invert embeddings to text without using gradients
logit2prompt (morris, …, rush, 2024) - recover prompt from output logits
output2prompt (zhang, morris, & shmatikov, 2024) - recover prompt from long text outputs (by building a model of the sparse encodings of the outputs)
ZSInvert: universal zero-shot embedding inversion (zhang, morris, & shmatikov, 2025) - beam search but keep prefixes that have best similarity with given embedding & train text-to-text correction model that helps refine hypotheses
builds on adversarial decoding (zhang, zhang, & shmatikov, 2024) - use beam search with multiple scorers besides just perplexity (e.g. for defense evasion)
On the Theoretical Limitations of Embedding-Based Retrieval (weller, boratko, naim & lee, 2025)
Multi-Vector Embeddings are Provably More Expressive than Single Vector Embeddings (jayaram, 2026)
Quantifying and Expanding the Theoretical Capacity of Late-Interaction Retrieval Models (killingback, ingale, zamani & musco, 2026) - MaxSim exactly replicates non-negative inner products and extend it for exact real-valued products, improving negation queries.
External memory enhancements for LLMs#
Ways to give an LLM memory beyond its context window: a kNN index over past context, a datastore read at inference time, a separate model trained on a corpus in place of retrieval, or a memory matrix the network reads and writes. Hopfield networks connect this to attention.
The AI Hippocampus: How Far are We From Human Memory? (jia…zhu, 2026)
delineate implicit memory (neocortex, learned weights), explicit memory (hippocampus, episodic memory/RAG), agentic memory (PFC, state and scratchpad)
Memex(RL): Scaling Long-Horizon LLM Agents via Indexed Experience Memory (wang…wei, 2026)
Engram: Conditional Memory via Scalable Lookup: A New Axis of Sparsity for LLMs (cheng…liang; deepseek, 2026)
STEM: Scaling Transformers with Embedding Modules (sadhukhan…chen, 2026)
MeMo: Memory as a Model (quek…solar-lezama, 2026) - train a model to learn a corpus (replacing retrieval piece in RAG), and then use it along with a frozen LLM to retrieve knowledge
memorizing transformers (wu…szegedy, 2022) - knn-based learned indexing + retrieval at training time
at test time, you just need to index the entire context and the model will be able to use it
kNN Prompting: Learning Beyond the Context with Nearest Neighbor Inference (xu…zhang, 2023) - instead of verbalizer, use nearest-neighbor (nice results for dbpedia)
kNN-Prompt: Nearest Neighbor Zero-Shot Inference (shi…zettlemoyer, 2022)
Memory Networks (weston, chopra, & bordes, 2014) - external KB that can be read / written to (stores plain text)
End-To-End Memory Networks (sukhbaatar, szlam, weston, & fergus, 2015) - trained with less supervision for memory reading/writing
SILO LMs: Isolating Legal Risk In a Nonparametric Datastore (min…smith, zettlemoyer, 2023)
Use a parametric LM on open data then one of 2 nonparametric datastores: kNN LM or retrieval in-context
A Soft and Fast Pattern Matcher for Billion-Scale Corpus Searches (deguchi…yokoi, 2025)
Hybrid computing using a neural network with dynamic external memory (graves…hassabis, 2016) [see blog post]
differentiable neural computer (DNC) - neural network that can read from and write to an external memory matrix
stores external memory matrix
reads from memory via multiplying by a vector (e.g. one-hot vector would yield single element)
extends Neural turing machines (graves, wayne, & danihelka, 2014)
Hopfield Networks is All You Need (ramsaeur…hochreiter, 2020)
keys: each input has a key vector which “represents info about this input” (e.g. this is a noun)
queries: each input has a query vector which “asks for other inputs that would be useful context” (e.g. what adjectives describe this word)
in self-attention these queries also come from the input whereas in just regular attention they come from somewhere else (e.g. the output of a translation task)
transformer finds similarity between each key with each query then takes softmax - this provides weights for each of the inputs, as context for the original input
in transformer, these weights are used to weight the values but in hopfield nets we would take a weighted sum of the keys and feed it back as the input
as we update becomes more skewed towards the things that match the most
pre-transformers
Improving Neural LMs with a Continuous Cache (grave…usunier, 2016) - cache previous embeddings as memory from a document to contextualize an LSTM
Key ideas
The first design choice is where query and document interact, separately (bi-encoder), per token (late interaction) or together (cross-encoder), which trades indexing ahead of time against accuracy.
Most strong models end their training with contrastive finetuning, and the temperature in InfoNCE decides how much the hardest negatives count.
Approximate nearest-neighbor indexes build a structure once and search only a small part of it per query, while product quantization makes each comparison cheaper.
Benchmarks like MTEB may be overfit, and agentic search results suggest grep over the raw corpus can match vector retrieval.
Embeddings can be made interpretable from yes/no questions, can leak their input text, and look similar across different models.