
LLMs#
How a transformer works, from the shape of each matrix to self-attention, and a reading list of foundational transformer-based models.
About this chapter
The chapter opens with two diagrams of a decoder-only transformer. The first tracks the shape of every matrix from input tokens to next-token probabilities; the second shows how KV caching reuses keys and values while generating. If attention is new to you, read these together with the section “visual explanation of self-attention”, which works one example through by hand.
The middle of the chapter is a reading list of influential models grouped by area (language, vision, text-vision, RL, code, science, audio), followed by n-gram language models such as infini-gram. The later sections give the formal view of transformers after Phuong & Hutter, the three families of models (GPT-like, BERT-like, BART/T5-like), and the RNN seq2seq models that came before.
See related papers in the 📌 llm research and 📌 interpretability pages.
Basics#
Two diagrams to keep in mind: the shape of every matrix in a decoder-only transformer, and how KV caching saves work during generation. The bullets give the one-line meaning of attention: estimate an element as a weighted sum of the values of the elements it attends to.
Here is my best diagram of essential components of transformer sizes (I find it very useful to remember the shapes of all the matrices):

Fig. 85 Figure 1. A decoder-only transformer with the shape of every matrix. \(T\) tokens become a \(T \times D\) embedding, plus positional encodings. Each layer adds a self-attention output and an MLP output to it, so the shape stays \(T \times D\), and the last layer is projected to \(T \times \vert Voc \vert\) next-token probabilities. The inset opens one layer: \(QK^T\) gives the \(T \times T\) attention scores, masked so tokens only see earlier tokens, and \(H\) heads of size \(D'\) are concatenated.#
Note that query is “what is the token looking for” and key is more like the index
Here is a follow-up diagram showing how key-value caching works during inference to speed things up:

Fig. 86 Figure 2. KV caching. When generating the next token, the keys and values of earlier tokens (purple) come from a cache. Only the new token’s row (red) of Q, K, V, the attention scores and the outputs has to be computed.#
attention = vector of importance weights
to predict or infer one element, such as a pixel in an image or a word in a sentence, we estimate using the attention vector how strongly it is correlated with (or “attends to” other elements and take the sum of their values weighted by the attention vector as the approximation of the target
vanilla transformer: multihead attention, add + norm, position-wise ffn, add + norm
self-attention layer implementation, mathematics, and chandan’s self-attention cheat-sheet
Historically influential transformer-based models#
A reading list rather than a history to read in order. Indented papers are related to the paper above them: variants, predecessors or follow-ups.
nlp (see also this link)
early papers
attention is all you need (vaswani et al. 2017) - initial transformer
encoder-decoder transformer for seq-to-seq (most new models don’t have special encoder-decoder structure for translation)
Semi-supervised Sequence Learning (dai & quoc le, 2015) - context vector is weighted sum of context vector at each word
ULMFiT (howard & ruder, 2018)
BERT (devlin et al. 2018) - semi-supervised learning (predict masked word - this is bidirectional) + supervised finetuning
RoBERTa (liu et al. 2019)
BART (lewis et al. 2019) - generalizes BERT with sequence-to-squence training: train by (1) corrupting text then (2) reconstruct the original text
ELMo (peters…zettlemoyer, 2018) - no word embeddings - train embeddings w/ bidirectional lstm (on language modeling)
XLNet (yang…quoc le, 2020)
GPT-4 (openai, 2023) - adds multimodal understanding + boosts context length to 32k
GPT-4o - adds more multimodality for input/output
GPT-3 (brown et al. 2020) - identical to GPT-2 except larger and replaces dense attention with sparse attention
sizes: largest has 175B params, 96 layers, 96 heads in each layer, head with dim 128, vocab size ~50k
InstructGPT (ouyang…lowe, 2022)
GPT-2 (radford et al. 2018)
GPT (radford et al. 2018)
Gopher (deepmind, 2021) - basically gpt-3 with slight mods (replace layernorm by RMSnorm, different positional embeddings)
open-source (from meta ai): LlaMa 2, LLaMa, OPT-IML, OPT
GPT4All (LLaMA 7B finetuned on code/stories/dialogue)
ELECTRA: Pre-training Text Encoders as Discriminators Rather Than Generators (clark…quoc le, chris manning, 2020) - more efficient: rather than standard masked training, use generator-discriminator setup for “token detection”
generator replaces many masked tokens with plausible samples - train with MLM
discriminator tries to guess which tokens were the masked ones - this is the main model that gets used
LongNet: Scaling Transformers to 1,000,000,000 Tokens (ding, …, wei, 2023) - multiscale attention similar to wavelets
Longformer: The Long-Document Transformer (beltagy, peters, & cohan 2020) - processes very long contexts
PaLM: Scaling Language Modeling with Pathways (google 2022) - 540 Billion params
pathways hardware center allows for fast/efficient training
discontinuous improvements - at some point large model improves
Chinchilla: Training Compute-Optimal LLMs (deepmind 2022)
“chinchilla scaling laws” - for compute-optimal training, the model size and the number of training tokens should be scaled equally
T0 (sanh…rush, 2022) - multitask training enables better zero-shot generalization
T5 (raffel…liu, 2020) – text-to-text transfer transformer
UL2: Unifying Language Learning Paradigms (tay…metzler, 2022) - open-source 20B model, beats GPT-3 at zero-shot
early instruction following
FLAN-PaLM: Scaling Instruction-Finetuned Language Models (chung, …, quoc le, jason wei, 2022) - finetune with datasets phrased as instructions
FLAN (wei, …, le, 2021) - finetune on instructions to follows instructions
subquadratic attention
MAMBA (gu & dao, 2023) - state-space model
reasoning models
O1, O3, Deepseek-R1, …
smaller newer models
phi-1, phi-2
mistral 7B, mixtral MoE
clinical
ClinicalGPT: LLMs Finetuned with Diverse Medical Data and Comprehensive Evaluation (wang, …, li, 2023)
BioGPT (luo…poon, liu, 2022)
ChatDoctor (finetuned LLAMA) (yunxiang, …, you, 2023)
PubMedGPT (2.7B): (bolton, hall, …, manning, liang, 2022) -> renamed to BioMedLM
BioBERT: A pre-trained biomedical language representation model for biomedical text mining (2019)
PubMedBERT: Domain-Specific Language Model Pretraining for Biomedical Natural Language Processing (gu…gao, poon, 2021)
Med-PaLM 2 (google, 2023) - state of the art QA
LLMs Encode Clinical Knowledge (singhal, …, natarajan, 2022, google/deepmind) - introduce MultiMedQA dataset + derive Med-PaLM, a prompt-tuned version of PaLM
PMC-LLaMA (wu et al. 2023)
paper parsing
Nougat: Neural Optical Understanding for Academic Documents (blecher…scialom, sojnic, 2023)
PDFTriage: Question Answering over Long, Structured Documents (adobe, 2023)
other
text-vision models
CLIP (radford et al. 2021) - jointly train text/images
batch-based loss: encodings from same image/text pair should be close while encodings across different examples in the batch should be different
note: empirically works better with very large batch size
DALL-E 2 (openai, 2022)
clip is foundation as generative model
generates text + image embeddings
“prior network” maps text embedding to image embedding
adds diffusion model
Stable diffusion (stability.ai, 2022) - open-source recreation, now highly optimized for speed
Imagen (google, 2022)
BLIP-2 (salesforce, 2023) - Bootstrapping Language-Image Pre-training with Frozen Image Encoders and LLMs
video
Text-To-4D Dynamic Scene Generation (meta, 2023)
vision (rather than words, people generally use image patches as tokens)
VIT: An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale (dosoviskiy, …, houlsby, 2020)
attention augmentation to resnet for vision (bello…quoc le, 2020)
DINOv2 (FAIR, 2022)
DINO: Emerging Properties in Self-Supervised Vision Transformers (FAIR, 2021)
SAM 2 (FAIR, 2024) - strong segmentation model (handles 2D images or 2D images + time)
SAM 1 (FAIR, 2023) - segmentation for 2D images
Masked Autoencoders Are Scalable Vision Learners (he…dollar, girshick, 2021) - BERT-style training
speed up by not applying encoder to mask tokens + adding mask to a lot of the data (like 75%)
really good results without much data
spatial transformers networks (deepmind, 2015)
-
AdA: Human-Timescale Adaptation in an Open-Ended Task Space (deepmind, 2023)
GATO: A Generalist Agent (deepmind, 2022) - single agent plays many different video games
different modalities are converted to tokens differently (e.g. image patches are fed through resnet)
In-context Reinforcement Learning with Algorithm Distillation (laskin, wang, …, sahni, satinder singh, mnih, 2022, deepmind) - learn to improve an RL algorithm
put history of (observation, action, reward) sequences into context and then use them to predict new action given new observation
Decision Transformer: Reinforcement Learning via Sequence Modeling (chen, lu, …abbeel, srinivas, mordatch, 2021) - transformer that predicts what the next highest reward step is instead of the next word
agents
AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation (wu, bansal, …, wang, 2024)
dialog
ChatGPT
GODEL: Large-Scale Pre-Training for Goal-Directed Dialog (baolin peng, galley, …, gao , 2022) - add grounded pre-training
Deal or No Deal? End-to-End Learning for Negotiation Dialogues (lewis…batra, 2017, Meta ) - controversial paper where agents “make up their own language” (this is pre-transformers)
MINERVA: Solving Quantitative Reasoning Problems with Language Models (google, 2022) - train on well-parsed, domain-specific data (math arxiv) to solve math-reasoning problems
autoformalization (wu…, szegedy, 2022) - translating from natural language math to formal language
produce sql/python that then finds an answer (cheng…zettlemoyer, smith, yu, 2022)
CODEX: Evaluating LLMs Trained on Code (2021, openai)
Repair Is Nearly Generation: Multilingual Program Repair with LLMs (joshi et al. 2022)
Improving automatically generated code from Codex via Automated Program Repair (fan et al. 2022) - use automated program repair to tweak codex outputs to make them better
Generating Question Titles for Stack Overflow from Mined Code Snippets (gao et al. 2020)
Automatic Program Repair with OpenAI’s Codex: Evaluating QuixBugs (prenner & robbes, 2021)
use prompt like:
### fix the bug in the following function
<buggy function and/or docstring here>
### fixed function
program synthesis arxiv.org/abs/2108.07732 - formalize natural language into runnable code
science
Galactica: A LLM for Science (taylor…, stojnic, 2022, meta ai) - trained on mostly papers + some knowledge bases (e.g. proteins)
Nougat: Neural Optical Understanding for Academic Documents (blecher…scialom, sojnic, 2023)
audio
MusicLM: Generating Music From Text (google, 2023)
Jukebox: A Generative Model for Music (openai, 2020)
Voicebox: Text-Guided Multilingual Universal Speech Generation at Scale (meta, 2023) - text-to-speech
summarization / keywords
KeyBERT: Minimal keyword extraction with BERT ([grootendorst, 2020]
Ngram-based models#
An n-gram model predicts the next token from counts of what followed the same context in the training data. Infini-gram scales this up with backoff (use the longest context that appears in the corpus) and a suffix array for fast counting.
Infini-gram: Scaling Unbounded n-gram Language Models to a Trillion Tokens (liu, min, zettlemoyer, choic, & hajishirzi, 2024)
motivation: hard to scale ngram models to large datasets and large data lengths
soln 1: backoff (jurafsky & martin, 2000) - select n based on the longest suffix of the prompt that has a non-zero count in the corpus
counts of the next token yield the prob. of the next token
Katz backoff (katz, 1987) discounts probs to yield valid prob. distr.
soln 2: represent prob. table in suffix array to make things very fast
suffix array stores address to each location in the training data alphabetically sorted
roughly the same size
this makes it fast to search for instances of an ngram (and also for what precedes/follows it)
results show that infinigram can considerably improve perplexities when it is linearly combined with the logits from LLMs (experiments up to llama-2 70B)
Interpretable Language Modeling via Induction-head Ngram Models (kim, mantena, …, gao, 2024) - extend infinigram with fuzzy-matching induction heads to improve adaptation
Transformers Can Represent n-gram Language Models (svete & cotterell, 2024) - transformers have the computational capacity to represent ngram models
Generalization through Memorization: Nearest Neighbor Language Models (khandelwal, levy, jurafsky, zettlemoyer, & lewis, 2020) - average over output of neighboring embeddings
smoothing ngram models (chen & goodman, 1996)
interpolation - e.g. linearly combine pobabilities shorter ngram sequences with larger ngram sequences (places better prior on ngrams that were not seen)
see also latent LM for smoothing
Improving N-gram Language Models with Pre-trained Deep Transformer(wang et al. 2019 ) - use transformer to generate synthetic data for new n-gram model (language model, doesn’t extend to classification)
Improvements to N-gram Language Model Using Text Generated from Neural Language Model (suzuki et al. 2019) - generate synthetic data from RNNs for new n-gram model
classifierss
Aug-imodels: Augmenting Interpretable Models with LLMs during Training (singh, askari, caruana, & gao, 2023) - build fully transparent n-gram based classifiers (linear or tree) by distilling info from LLMs
fasttext (jin et al. 2016)
Neural Bag-of-Ngrams (li et al. 2017) - learn embedding vectors for ngrams via deep version of skip-gram
Mathematical overview of transformers#
The notation of Phuong & Hutter in brief: the two tasks, how tokens become vectors, the three kinds of attention, and how the last hidden state becomes a prediction.
based on Formal Algorithms for Transformers (phuong & hutter 2022)
tasks
sequence modeling: learn \(p(x)\), usually factorized as \(p(x_i\vert x_1,...,x_{i-1})\)
sequence-to-sequence: learn \(p(z\vert x)\), e.g. transalation, speech-to-text, question answering
preprocessing
embedding matrix takes in one-hot tokens and linearly maps them to a vector
positional embedding of a token is usually added to the token embedding to form a token’s initial embedding
attention types
Bidirectional / unmasked self-attention - primary/context vectors are the same
Unidirectional / masked self-attention - mask scores from before a given word
Cross-attention - primary/context vectors can come from different places
non-attention
layernorm: controls mean/variance of activations
RMSnorm: simpler version, sets mean/offset to zero
unembedding
linear layer (with softmax) that outputs size of original vocab
sometimes fixed to be transpose of the embedding matrix
predictions
predict next word using single linear layer on hidden state from previous word
finetune classification head often only using linear layer on first token from sequence
architectures
initially, encoder-decoder was common, but now often no decoder
Visual explanation of self-attention#
Each token emits a query, a key and a value. A token’s output is a weighted sum of all the values, with weights from a softmax over its query’s dot products with every key. The figure below works this out for a two-token input.
based on article by jay allamar
self-attention - layer that lets word learn its relation to other layers
for each word, want score telling how much importance to place on each other word (queries \(\cdot\) keys)
we get an encoding for each word
the encoding of each word returns a weighted sum of the values of the words (the current word gets the highest weight)
softmax this and use it to do weighted sum of values
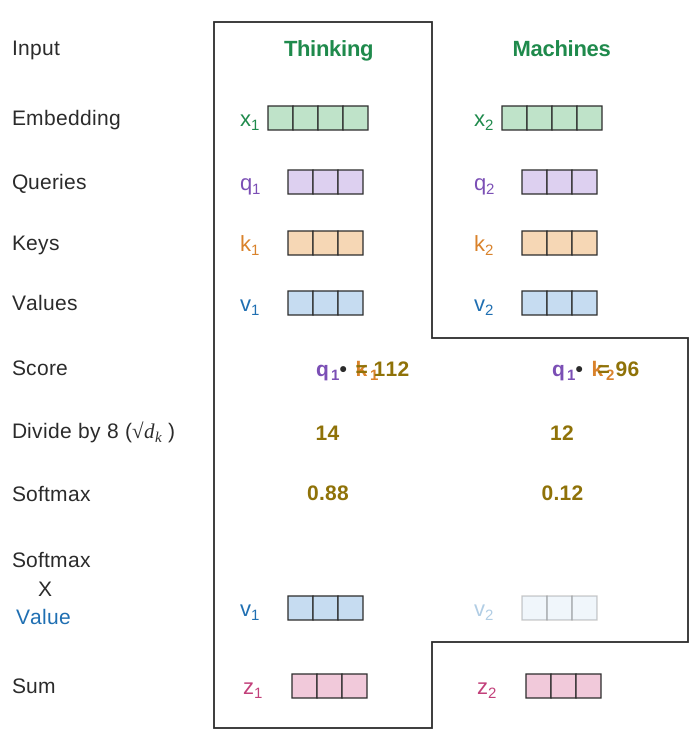
Fig. 87 Figure 3. Self-attention for the two-token input “Thinking Machines”, at the first position. The scores \(q_1 \cdot k_1 = 112\) and \(q_1 \cdot k_2 = 96\) are divided by 8 (\(\sqrt{d_k}\)) and softmaxed into weights 0.88 and 0.12. The output \(z_1\) is the weighted sum of the values.#
(optional) implementation details
multi-headed attention - just like having many filters, get many encodings for each word
each one can take input as the embedding from the previous attention layer
position vector - add this into the embedding of each word (so words know how far apart they are) - usually use sin/cos rather than actual position number
padding mask - add zeros to the end of the sequence
look-ahead mask - might want to mask to only use previous words (e.g. if our final task is decoding)
residual + normalize - after self-attention layer, often have residual connection to previous input, which gets added then normalized
decoder - each word only allowed to attend to previous positions
3 components
queries
keys
values
attention
encoder reads input and ouputs context vector after each word
decoder at each step uses a different weighted combination of these context vectors
specifically, at each step, decoder concatenates its hidden state w/ the attention vector (the weighted combination of the context vectors)
this is fed to a feedforward net to output a word
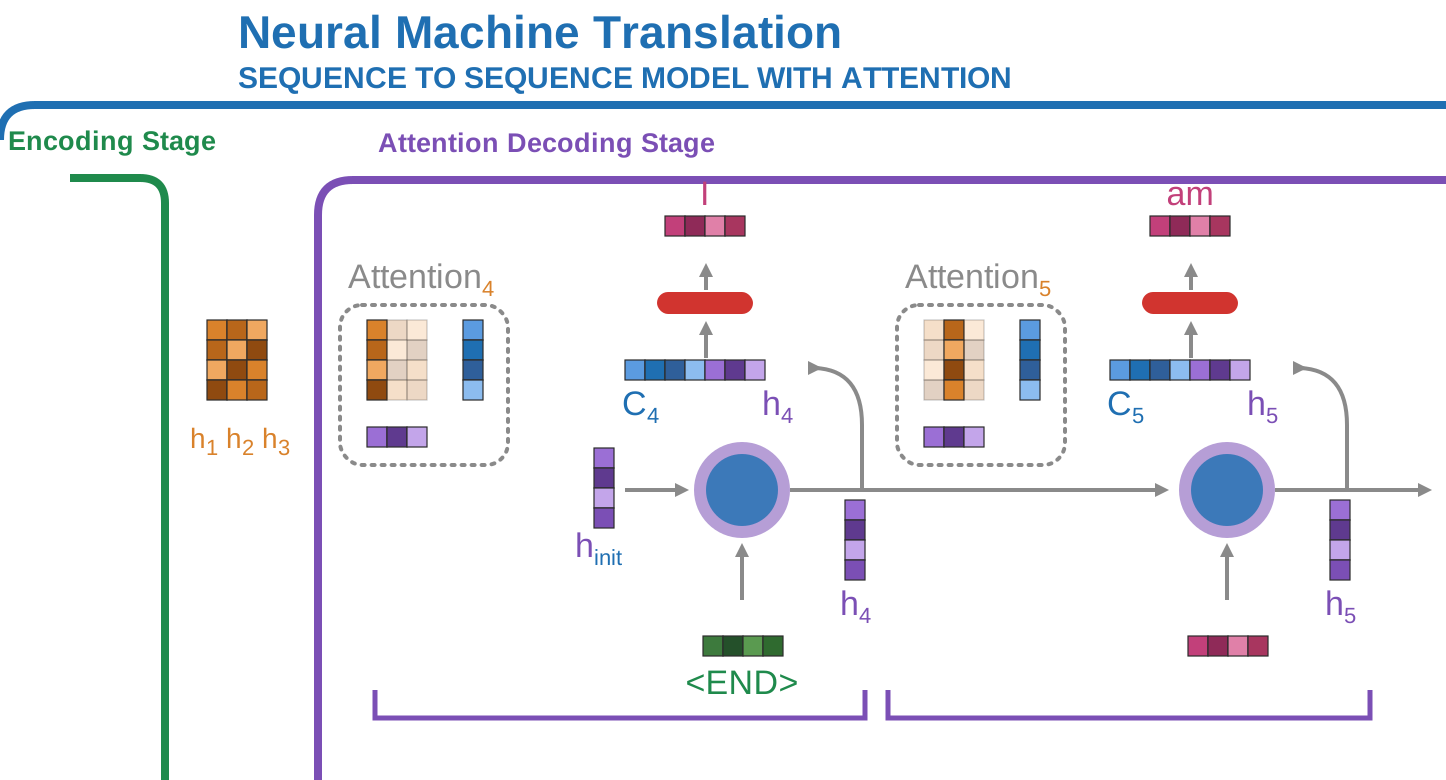
Fig. 88 Figure 4. Decoding in a seq2seq model with attention. At each step the decoder’s hidden state scores the encoder states \(h_1, h_2, h_3\) to form a context vector \(C\); the context vector and the hidden state are concatenated and passed through a feed-forward layer to output the next word.#
at a high level we have \(Q, K, V\) and compute \(\text{softmax}(QK^T)V\)
instead could simplify it and do \(\text{softmax}(XX^T)V\) - this would then be based on kernel
transformer
uses many self-attention layers
many stacked layers in encoder + decoder (not rnn: self-attention + feed forward)
details
initial encoding: each word -> vector
each layer takes a list of fixed size (hyperparameter e.g. length of longest sentence) and outputs a list of that same fixed size (so one output for each word)
can easily train with a masked word to predict the word at the predicted position in the encoding
multi-headed attention has several of each of these (then just concat them)
Huggingface tutorial#
The three families differ in what they are trained to predict. GPT-like models predict the next token from the earlier ones, BERT-like models fill in masked tokens using both sides, and BART/T5-like models map an input sequence to an output sequence.
Broadly, models can be grouped into three categories:
GPT-like (also called auto-regressive Transformer models)
BERT-like (also called auto-encoding Transformer models)
BART/T5-like (also called sequence-to-sequence Transformer models)
Handling multiple sequences - Hugging Face Course
pad sequences to have the same length (need to modify attention masks to ignore the padded values)
Pre-transformer nlp models#
Before transformers, seq2seq models were RNNs: an encoder compressed the input into one context vector and a decoder generated from it. The attention section above shows the fix, letting the decoder look at every encoder state.
rnns
when training rnn, accumulate gradients over sequence and then update all at once
stacked rnns have outputs of rnns feed into another rnn
bidirectional rnn - one rnn left to right and another right to left (can concatenate, add, etc.)
standard seq2seq
encoder reads input and outputs context vector (the hidden state)
decoder (rnn) takes this context vector and generates a sequencefagoa
Key ideas
A decoder-only transformer keeps a \(T \times D\) matrix through every layer. Each layer adds an attention output and an MLP output to it, and the last layer is projected to next-token probabilities over the vocabulary.
In self-attention each token’s output is a weighted sum of all the values, with weights from a softmax over its query’s dot products with the keys, divided by \(\sqrt{d}\).
With a causal mask each token sees only earlier tokens, and KV caching reuses the earlier keys and values so each generation step computes only the new token’s row.
{‘Transformer models come in three families’: ‘GPT-like (auto-regressive), BERT-like (auto-encoding) and BART/T5-like (sequence-to-sequence).’}
An n-gram model predicts the next token from counts. Infini-gram uses the longest suffix of the prompt found in the corpus, counts with a suffix array, and improves an LLM’s perplexity when the two are combined.