
Complexity#
Some papers on measuring model complexity, from learning theory to double descent and MDL.
About this chapter
Complexity comes up whenever you ask whether a model can be interpreted, how many samples it needs, or whether it fits the problem. The page starts with philosophy, where complexity is a mix of order and disorder that depends on how a system is described, then lists the standard measures: computational complexity, Bayesian criteria (AIC, BIC), VC dimension, and a long list of other definitions.
Two sections matter most for modern models. Double descent shows that test risk can fall again once a model has more parameters than samples, so parameter count alone is a poor measure of complexity. Minimum description length (MDL) gives a different measure: the best model is the one that gives the shortest code for the data plus the model, which splits the cost into noise and learnable information.
Chapter outline: 10 sections
- Philosophy1 figureDefinitions of complexity from outside statistics.
- Computational complexityThe first of the standard measures: the resources an algorithm needs to solve a class of problems, such as its run time.
- Bayesian model complexityCriteria that score a model by its fit plus a penalty for complexity, such as AIC and BIC.
- Statistical learning theory
- MiscShort entries on the Rashomon set (many near-equally accurate models) and a list of complexity measures from physics, information theory and neuroscience.
- Estimated
- Entropy characterizationsMeasure a function class by how many small balls (metric entropy) or brackets (bracket entropy) it takes to cover it.
- Deep learning complexityMeasures meant for deep nets, where counting parameters says little.
- Double descent1 interactiveClassical intuition says test risk rises once a model can interpolate the training data.
- Minimum description lengthMDL treats model selection as compression.
Complexity can be a useful notion for many things in statistical models. It can help answer the following questions:
can I interpret this model?
how many samples should I collect?
is my model a good fit for this problem?
model class selectiondirectionsmore stable (e.g. LOOCV, deletion, weights)interpolating estimator w/ lowest var?
set an err threshold and then look at stability
Philosophy#
Definitions of complexity from outside statistics. Common threads: complexity is only useful for comparison, depends on the description and the goal, and is highest between perfect order and pure randomness.
the architecture of complexity (herbert simon, 1962)
complexity takes the form of hierarchy
simon, 1981: complex systems are “made up of a large number of parts that have many interactions.”
What is complexity? (edmonds 95)
complexity is only really useful for comparisons
properties
size - makes things potentially complex
ignorance - complex things represent things we don’t understand (e.g. the brain)
minimum description size - more about information than complexity
potential problem - expressions are not much more complex than the original axioms in the system, even though they can get quite complex
potential problem - things with lots of useless info would seem more complex
some variety is necessary but not sufficient
order - we sometimes find order comes and goes (like double descent) - has a lot to do with language (audience)
defn: “that property of a language expression which makes it difficult to formulate its overall behaviour even when given almost complete information about its atomic components and their inter-relations”
language matters - what about the system are we describing?
goal matters - what outcome are interested in?
On Complexity and Emergence (standish 01)
definition close to Kolmogorov / shannon entropy
adds context dependence
kolmogorov complexity = algorithmic information complexity
problem 1: must assume a particular Universal Turing machine (which might give differing results)
problem 2: random sequences have max complexity, even though they contain no information
soln
incorporate context - what descriptions are the same?
\(C(x) = \lim _{\ell \to \infty} \log_2 N - \log_2 \omega (\ell, x)\)
where C(x) is the complexity (measured in bits), \(\ell(x)\) the length of the description, N the size of the alphabet used to encode the description and ω(ℓ,x) the size of the class of all descriptions of length less than ℓ equivalent to x.
emergence - ex. game of life
What is complexity 2 (gell-mann 02)
AIC - algorithmic information content - contains 2 terms
effective complexity (EC) = the length of a very concise description of an entity’s regularities
regularities are judged subjectively (e.g. birds would judge a bird song’s regularity)
2nd term relating to random features
complexity (sporns 07)
complexity = degree to which components engage in organized structured interactions
High complexity -> mixture of order and disorder (randomness and regularity) + have a high capacity to generate emergent phenomena.
2 categories
algorithmic / mdl
natural complexity (e.g. physical complexity)
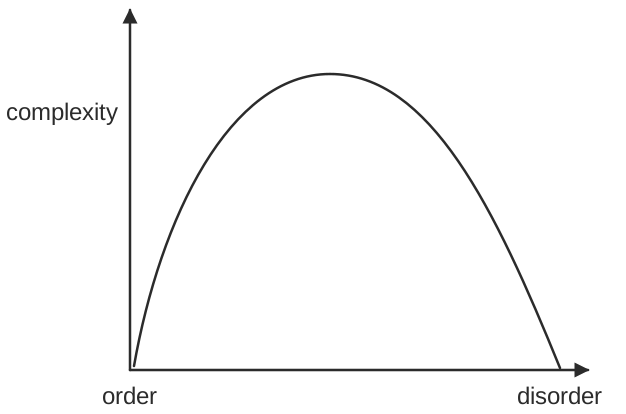
Fig. 204 Figure 1. Complexity is low for a perfectly ordered system and for a fully random one, and highest in between, where regularity and randomness mix.#
-
“the probability of producing some types of outputs is far greater when randomness operates at the level of the program describing it rather than at the level of the output itself”
“they recently reported in Royal Society Open Science that, compared to statistically random mutations, this mutational bias caused the networks to evolve toward solutions significantly faster.”
Computational complexity#
The first of the standard measures: the resources an algorithm needs to solve a class of problems, such as its run time. Parameterized complexity isolates part of the input into a parameter to handle problems that are NP-hard or worse.
amount of computational resource that it takes to solve a class of problem
Computational complexity (papadimitriou)
like run times of algorithms etc. \(O(n)\)
Parameterized complexity (downey and fellows)
want to solve problems that are NP-hard or worse, so we isolate input into a parameter
Bayesian model complexity#
Criteria that score a model by its fit plus a penalty for complexity, such as AIC and BIC. BIC comes back in the MDL section as the penalty that MDL gives for OLS.
Bayesian measures of model complexity and fit (spiegelhalter et al.)
AIC
BIC
Statistical learning theory#
VC-dimension - measure of capacity of a function class that can be learned
cardinality of largest number of points which can be shattered
Misc#
Short entries on the Rashomon set (many near-equally accurate models) and a list of complexity measures from physics, information theory and neuroscience.
rashomon curves (semenova & rudin, 2019)
rashomon effect - many different explanations exist for same phenomenon
rashomon set - set of almost-equally accurate models for a given problem
rashomon ratio - ratio of volume of set of accurate models to the volume of the hypothesis space
rashomon curve - empirical risk vs rashomon ratio
rashomon elbow - maximize rashomon ratio while minimizing risk
good for model selection
bennet’s logical depth (1988) - computational resources taken to calculate the results of a minimal length problem (combines computational complexity w/ kolmogorov complexity)
Effective measure complexity (Grassberger, 1986) quantifies the complexity of a sequence by the amount of information contained in a given part of the sequence that is needed to predict the next symbol
Thermodynamic depth (Lloyd and Pagels, 1988) relates the entropy of a system to the number of possible historical paths that led to its observed state
lofgren’s interpretation and descriptive complexity
convert between system and description
kaffman’s number of conflicting constraints
Effective complexity (Gell-Mann, 1995) measures the minimal description length of a system’s regularities
Physical complexity (Adami and Cerf, 2000) is related to effective complexity and is designed to estimate the complexity of any sequence of symbols that is about a physical world or environment
Statistical complexity (Crutchfield and Young, 1989) is a component of a broader theoretic framework known as computational mechanics, and can be calculated directly from empirical data
Neural complexity (Tononi et al., 1994) - multivariate extension of mutual information that estimates the total amount of statistical structure within an arbitrarily large system.= the difference between the sum of the component’s individual entropies and the joint entropy of the system as a whole
complexity = variance of the model predictions (given that there is zero bias)
Estimated#
optimal m estimation in high dimensions optimal loss function (optimize over different loss functions, but evaluate with L2)assumes unbiased (so variance is the mse)
Entropy characterizations#
Measure a function class by how many small balls (metric entropy) or brackets (bracket entropy) it takes to cover it. This can be done for a whole class or only for the functions visited during training.
try to characterize functions in the prediction space
metric entropy - want functions to be close (within epsilon)
bracket entropy - function is both upper and lower bounded by bounding functions, which are within epsilon
can do this on an entire function class (e.g. all neural networks) or on a restricted subset (e.g. path during training)
optimal learning via local entropies and sample compression (zhivotovskiy 2017)
risk bounds for statistical learning (massart & nédélec 2007)
Chaining Mutual Information and Tightening Generalization Bounds (asadi et al. 2018)
describing DNN paths
Online Regularized Nonlinear Acceleration (scieur et al. 2018)
Deep learning complexity#
Measures meant for deep nets, where counting parameters says little. One uses the Hessian and ties complexity to how smooth the function is with respect to an augmented loss.
a hessian-based complexity measure for dnns (lejeune et al. 2019) with generalization and computation to a different form of stability
thm 3 - want function to be smooth wrt to augmented loss
complexity measure (liang et al. 2019)
Double descent#
Classical intuition says test risk rises once a model can interpolate the training data. For min-norm least squares with \(p\) features and \(n\) samples, Hastie et al. give the limiting risk as a function of \(\gamma = p/n\): it blows up at \(\gamma = 1\), where the model just barely interpolates, and comes down again for \(\gamma > 1\).
Reconciling modern machine learning and the bias-variance trade-off (belkin et al. 2018)
Surprises in High-Dimensional Ridgeless Least Squares Interpolation (hastie et al. 2019)
main result of limiting risk, where \(\gamma \in (0, \infty)\):
\(R(\gamma) = \begin{cases} \sigma^2 \frac{\gamma}{1-\gamma} & \gamma < 1\\ \vert \vert \beta\vert \vert _2^2(1 - \frac 1 \gamma) + \sigma^2 \frac{1} {\gamma - 1} & \gamma > 1\end{cases}\)
linear regression depends on data distr. (kuchibhotla et al. 2018)
two models of double descent for weak features (belkin et al. 2019)
Harmless interpolation of noisy data in regression (muthukumar et al. 2019) - bound on how well interpolative solns can generalize to fresh data (goes to zero with extra features)
Deep Double Descent: Where Bigger Models and More Data Hurt (nakkiran et al. 2019)
Linear models#
For linear models, degrees of freedom give a number for how much fitting a procedure does, which also works for procedures like ridge that don’t simply count parameters.
Degrees of Freedom and Model Search (tibshirani 2014)
degrees of freedom = quantitative description of the amount of fitting performed by a given procedure
linear smoothers and additive models (buja et al. 1989) see page 469 for degrees of freedom in ridge
Minimum description length#
MDL treats model selection as compression. A model that fits well gives short codes for the data, but the model’s parameters must be sent too, quantized to finite precision. For OLS this gives noise plus \((p/2) \log n\), the same penalty as BIC.
mdl in linear regression: want to send y over, X is known to both sides, theta is also sent (used to pick a decoder for y)
normalized maximum likelihood (nml): use theta to make codebook, then send code
The Minimum Description Length Principle in Coding and Modeling (barron, rissanen, & yu, 98)
mdl: represent an entire class of prob. distrs. as models by a single “universal” representative model such that it would be able to imitate the behavior of any model in the class. The best model class for a set of observed data, then, is the one whose representative premits the shortest coding of the data
tradeoff: “good” prob. models for the data permit shorter code lengths
generally agrees w/ low mse
ex. encode data w/ model defined by mle estimates, quantized optimally to finite precision, then encode estimate w/ prefix code
mdl
likelihood = summarize data in accodance / model (e.g. \(P(y\vert x, \theta)\))
parametric complexity = summarize model params
Model Selection and the Principle of Minimum Description Length (hansen & yu 2001)
mdl: choose the model that gives the shortest description of data
description length = length of binary string used to code the data
using a prob distr. for coding/description purposes doesn’t require that it actually generate our data
basic coding
set A, code C (mapping from A to a set of codewords)
Q is a distr. on A
\(-\log_2Q\) is the code length for symbols in A
can construct such a code w/ Huffman coding
expected code length is minimized when Q = P, the true distr of our data
different forms
2-stage
mixture
predictive
normalized maximum likelihood (NML)
mdl intro (rissanen, 2008) - scholarpedia
coding just the data would be like maximum likelihood
minimize \(\cblue{\underset{\text{log-likelihood}}{-\log P(y^n\vert x^n;\theta)}} + \corange{\underset{\text{description length}}{L(\theta)}}\)
ex. OLS
if we want to send all the coefficients, assume an order and \(L(\theta) = L(p) + L(\theta_1, ... \theta_p)\)
\(L(\theta) \approx \frac p 2 \log p\)
quantization for each parameter (must quantize otherwise need to specify infinite bits of precision)
if we want only a subset of the coefficients, also need to send \(L(i_1, ..., i_k)\) for the indexes of the non-zero coefficients
minimization becomes \(\underset p \min \quad [\cblue{\underset{\text{noise}}{- \log P(y^n\vert x^n; \hat{\theta}_{OLS})}} + \corange{\underset{\text{learnable info}}{(p/2) \log n}}]\)
noise - no more info can be extracted with this class of models
learnable info in the data = precisely the best model
stochastic complexity = noise + learnable info
in this case, is same as BIC but often different
modern mdl - don’t assume a model form, try to code the data as short as possible with a universal model class
often can actually construct these codes
Kolmogorov complexity \(K(x)\) = the shortest computer program (in binary) that generates x (a binary string) = the “amount of info” in x
complexity of a string x is at most its length
algorithmically random - any string whose length is close to \(\vert x\vert\)
more random = higher complexity
Minimum description length original reference \cite{rissanen1978modeling}. What is the minimum length description of the original?
MDL reviews \cite{barron1998minimum, hansen2001model}.
Book on stochastic complexity \cite{rissanen1989stochastic}
Minimum Description Length, MDL, principle for model selection, of which the original form states that the best model is the one which permits the shortest encoding of the data and the model itself
note: this type of complexity applies to the description, not the system
Look into the neurips paper on using mutual information and entropy and this paper by barron that related covering balls etc to minimax bounds
Information Theory in Probability Statistics Learning and Neural Nets (barron 97)
Information-Theoretic Asymptotics of Bayes Methods (clarke & barron 90)
MDL in non-linear models#
The same principle applied to tree pruning and neural nets, including a formulation that explains the double descent curve.
MDL-based Decision Tree Pruning (mehta et al. 95)
deep learning
high-level
most unsupervised learning can be thought of as mdl
to compress the data we must take advantage of mutual info between x and y
Learning Population Codes by Minimizing Description Length (zemel & hinton 1995)
Keeping Neural Networks Simple by Minimizing the Description Length of the Weights (hinton & van camp 1993)
The Description Length of Deep Learning Models (blier & ollivier 2018)
compress using prequential mdl
mdl for attention (lin 2019)
Lightlike Neuromanifolds, Occam’s Razor and Deep Learning (sun & nielsen 2019)
“A new MDL formulation which can explain the double descent risk curve of deep learning”
Towards Learning Convolutions from Scratch (neyshabur 2020)
uses some mdl as guiding principles
training with \(\beta\)-lasso, fc weights become very local
Key ideas
Complexity depends on how a system is described and what the description is for, and it is highest between perfect order and pure randomness.
The standard measures (computational complexity, AIC and BIC, VC dimension, metric entropy) each answer a different question, and the misc section lists many more.
Double descent shows that test risk can fall again once a model has more parameters than samples, so parameter count is a poor measure of complexity.
Minimum description length scores a model by the length of the code for the data plus the model, which splits the cost into noise and learnable information.